Prateek Agrawal Nov 17, 2026 No Comments
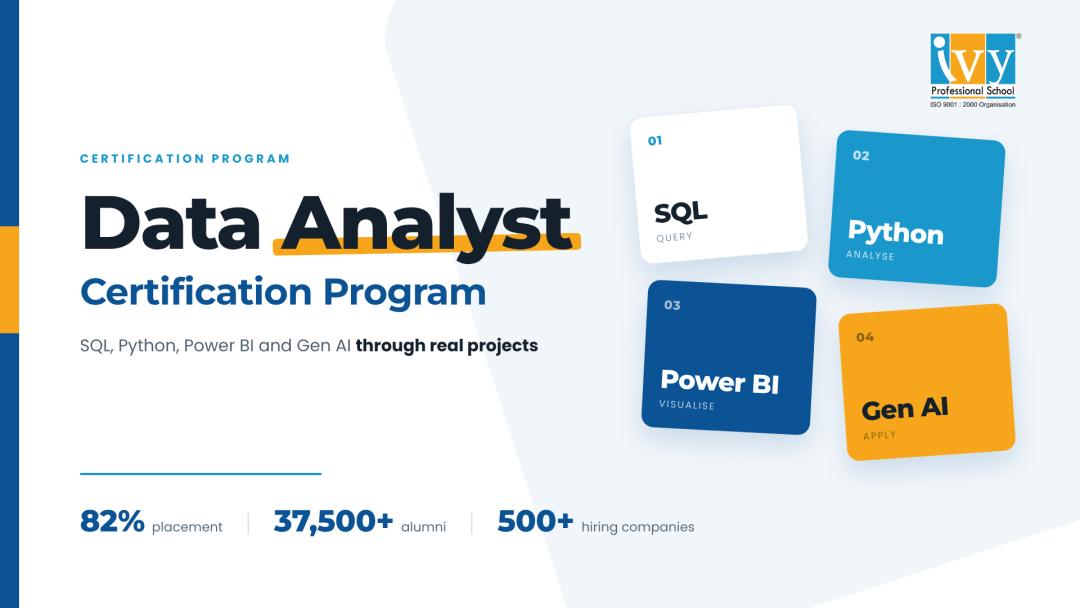
A data analyst certification program is often the fastest structured route into a data career. It gives you a clear syllabus, real tools and proof of skill that employers can check.
This guide explains what a good program teaches, how the learning path works, which tools matter, and what to expect on salary and placement. It is written for freshers, working professionals changing careers and aspiring data analysts.
Quick answer: The best data analyst certification program teaches SQL, Python, Power BI and Gen AI through real projects. It then helps you with your resume, mock interviews and hiring company introductions.
A data analyst certification program is a structured course that trains you in the skills a data analyst uses at work. It ends with an assessment, projects and a certificate.
The certificate alone does not get you hired. The skills, the projects and the placement support behind it do.
A certificate shows you attended a course. A certification shows you passed an assessment that tests real skill.
Employers value the second. Pick a data analyst certification program that tests you on queries, dashboards and case problems, not on memorised definitions.
Every team now works with data. Sales, finance, HR, marketing and operations all need a data analyst who can answer business questions with numbers.
A certification program gives you a faster and more focused path than studying alone. You follow a tested sequence, get feedback and build a portfolio.
Most job descriptions ask for the same core skills:
A good program covers all six and proves them through projects.
Three groups benefit most. Each starts from a different place.
If you have just finished a degree in commerce, science, engineering or arts, this program gives you a job-ready skill set. You do not need a coding background.
Many learners come from sales, operations, finance or teaching. Your domain knowledge is a real advantage. A finance executive who learns SQL and Power BI can move into a finance analytics role faster than most freshers.
If you already know some Excel or have tried free tutorials, a certification program fills the gaps. You get a fixed sequence, trainer feedback and projects you can show in interviews.
Use this table to compare programs before you pay any fee.
| Component | What it should cover | Why it matters |
| Excel and statistics | Formulas, pivot tables, probability | Builds analytical thinking |
| SQL | Joins, subqueries, window functions | Tested in most interviews |
| Python | pandas, NumPy, Matplotlib | Handles large, messy data |
| Power BI | Power Query, DAX, dashboards | Turns analysis into reports |
| Gen AI | Prompting, LLM tools, tokenization | Speeds up routine work |
| Capstone projects | End-to-end business problems | Gives proof of skill |
| Placement support | Resume, mock interviews, hiring partners | Turns skill into offers |
Sequence matters more than the number of topics. This path suits most learners.
Begin with Excel, basic statistics and how business data is structured. Learn to summarise numbers with averages, medians and distributions.
Do not skip this stage. Weak statistics is the main reason a new data analyst presents a confident chart with the wrong answer.
Most business data sits in databases, so SQL comes next. Learn to filter, group, join and rank data until you can answer a business question unaided.
Python lets you handle data that is too large or too messy for Excel. Learn it after SQL, once you already think in tables and filters.
Now learn to present your findings. Power BI turns your analysis into dashboards that managers read in minutes.
The final stage adds Gen AI skills, a capstone project and placement preparation. By now you can build something real and explain it clearly.
Tools change, but the thinking behind them lasts. Here is what you should be able to do with each one.
SQL is how you ask a database questions. Almost every data analyst interview has a SQL round.
Focus on these areas:
Practise on realistic tables such as orders, customers and products. Interviewers prefer clean queries over memorised syntax.
Python is the main programming language for analysis and automation. You use it to clean data, explore patterns and repeat work without manual effort.
Core libraries to learn:
A typical task is taking a large sales file, fixing dates, removing duplicates and finding the products that drive profit.
Power BI is widely used in Indian companies for dashboards that refresh automatically. A strong report answers one business question at a glance.
Key skills include:
If your manager needs a long explanation of your dashboard, redesign it.
Gen AI tools can draft SQL and Python, summarise reports and sort customer feedback into themes. They save time, but they also make mistakes.
Check every output against the data. A data analyst who verifies Gen AI output is faster. One who trusts it blindly is a risk.
Tokenization splits text into small units called tokens. A token can be a word, part of a word or a single character.
This matters to a data analyst for three reasons:
Knowing this helps you design better Gen AI workflows and avoid surprise costs.
Most learners need several months of regular study to become job-ready. The exact time depends on your starting point and the hours you can give each week.
Plan the learning path in stages and finish one project before starting another. Rushing through topics leaves gaps that interviews expose.
Be careful with promises of results in a few weeks. Real skill takes repeated practice on real data.
Tools get you shortlisted. Judgement gets you hired. Employers look for a few habits that no software teaches.
Know how the company makes money. A number matters only when you can link it to revenue, cost or customer experience.
Explain findings in plain words. Use one chart per point and one sentence per finding.
Ask why a number looks odd before you report it. A careful check catches errors that embarrass analysts later.
A capstone project separates a certificate from a skill. Recruiters want to see how you handle a full problem, from raw data to a recommendation.
| Project | Business question | Tools | What you deliver |
| Sales and profit dashboard | Which regions and products earn most? | SQL, Power BI | Interactive dashboard |
| Customer churn analysis | Why are customers leaving? | Python | Findings and a simple model |
| HR attrition study | Who is likely to resign? | Python, Power BI | Report with recommendations |
| Feedback analyser | What do customers complain about? | Python, Gen AI, tokenization | Summary of themes |
Put each project in a portfolio with a short write-up. State the problem, the data, your method and the result in plain language.
Add a link to your dashboard or code. A hiring manager should grasp your work in two minutes.
Pay depends on your city, skills, domain and the company. No data analyst certification program can promise a fixed salary, and you should be wary of any that does.
These factors usually raise the offer:
| Profile | What raises pay | Salary range per year (INR) |
| Fresher data analyst | SQL, Power BI, strong projects | ₹3.5 to 6 lakh |
| Career switcher | Domain knowledge plus data skills | No sourced range |
| Experienced data analyst | Python, Gen AI, business impact | ₹8 to 15 lakh |
Ivy Professional School reports a 67% average salary hike for learners who move into new roles after training. Your own result depends on your starting point and effort.
Placement support should be specific, not a vague promise. Ask every institute exactly what it does for you.
A useful data analyst certification program with placement includes:
Honest answers tell you more than any brochure.
Your first role is a starting point, not a ceiling. Most learners begin in one of a few common roles.
After two or three years, many analysts move into senior analyst, analytics manager or data science roles. Choose a domain early. An analyst who understands retail, banking or healthcare is harder to replace.
Imagine a retail manager asks why sales fell last month. A good analyst clarifies the question before opening a chart.
Follow this sequence:
The result is a one-page summary. The manager wants to know what happened and what to do next.
Your resume should show what you built, not only what you studied. Lead with projects, name the tools and state the result in one line.
Expect technical, case-based and behavioural rounds. Technical rounds test your queries and logic. Case rounds give you a business problem and ask how you would approach it.
Practise explaining a project aloud. If you cannot describe your dashboard in two minutes, the interviewer will notice.
Ivy Professional School has trained learners in data skills since 2008. These are the approved figures for our programmes.
| Measure | Figure |
| Experience | 18+ years (since 2008) |
| Alumni | 37,500+ |
| Trainers | 400+ |
| Hiring companies | 500+ |
| Placement | 82% |
| Average salary hike | 67% |
| Google rating | 4.8/5 from 2,250+ reviews |
| Recognition | Recognized by MeitY |
Classes run in Kolkata, Bangalore, Delhi, Pune and Mumbai, with an online option for learners elsewhere. The program focuses on SQL, Python, Power BI and Gen AI, with projects at every stage.
Many learners lose months to avoidable errors. Watch for these:
Depth beats breadth. Employers hire people who can finish a task.
Working professionals have less time but more context. A steady routine beats occasional long sessions.
Treat your job as a source of project ideas. A report you build for your team can become a portfolio piece.
Use this short checklist before you pay:
If most answers are yes, you are looking at a serious program.
Learning data skills takes steady effort over several months. Some people receive an offer quickly, and others need more projects and more interview practice.
That is normal. Keep building, keep applying and ask for feedback after every interview. Each round teaches you something the next round will reward.
Track progress in a simple sheet. Note each application, the interview stage reached and the topics you found hard. After ten interviews, the pattern shows you exactly what to revise.
No. A good program starts from the basics. Many successful analysts began with only Excel.
Learn SQL first. It is easier to start with and appears in almost every interview.
No program can guarantee a job. A good one improves your skills, portfolio and access to hiring companies, and your effort decides the rest.
Data analytics rewards steady practice. Choose a data analyst certification program that teaches SQL, Python, Power BI and Gen AI through real projects, and supports you all the way to the interview.
Start with one small project this week, share it with a mentor and improve it based on feedback. Small, consistent steps compound faster than learners expect.
If you are ready to start, speak to an Ivy counsellor and as

Prateek Agrawal Nov 14, 2026 No Comments
Every business decision today leans on data. Retailers decide what to stock using sales patterns, banks flag risk using transaction trends, and marketing teams judge campaigns by numbers rather than instinct. In 2026, companies of every size expect their people to read data, question it and act on it. That expectation has created steady demand for professionals who can turn raw numbers into clear recommendations.
If you are new to the field, the good news is that it is far more accessible than it looks. Many successful analysts began in commerce, finance, marketing, operations or even the arts. You do not need an engineering degree or prior coding experience. You need curiosity, comfort with basic numbers and a willingness to practise on real datasets.
This guide explains data analytics training for beginners in plain language. It covers what data analytics is, who benefits from learning it, the tools you will meet, a five-step roadmap for learning data analytics from scratch, how to judge a beginner data analytics course, the job roles open to you afterwards and the mistakes worth avoiding.
By the end, you will know what to learn first, what to leave for later and how to build proof of skill that employers trust.
Data analytics is the process of collecting, cleaning and examining data to find patterns that support better decisions. In plain English, it answers four questions: what happened, why it happened, what is likely to happen next and what we should do about it.
It matters because opinions are easy to argue with and numbers are easy to check. A store manager who knows which products sell on weekends, or a hospital administrator who can predict appointment no-shows, makes better calls than one working on guesswork. Analytics gives every decision an evidence trail.
Analysts work across four types of analytics:
Each type builds on the one before it, and each needs cleaner data and sharper questions than the last. Beginners spend most of their early months on descriptive and diagnostic work, and that is deliberate. These two types build the habits that later work depends on: cleaning data, asking sharp questions and checking numbers. Good data analytics training for beginners therefore starts here and builds upward.
Data analytics suits a wider range of people than most expect. Four profiles benefit the most.
Fresh graduates. A degree gives you subject knowledge, but employers hire for applied skills. Learning to clean, query and present data makes a graduate useful from the first week, whatever the degree.
Working professionals switching careers. If your current role feels limited, analytics offers a structured path into a growing function. Your previous industry experience becomes an advantage, because analysts who understand the business ask better questions.
Non-tech professionals. People in finance, marketing, commerce, HR and the arts already work with numbers or audiences. Adding analytics lets them replace manual reports with faster, more accurate analysis and move towards decision-making roles.
Business owners. Owners who can read their own sales, customer and cost data spot problems earlier and stop depending on others for basic reports. You do not need to become a full-time analyst to benefit.
The common thread is that none of these groups need to start as programmers. A well-designed beginner data analytics course assumes you are starting fresh and builds each skill on the one before it.
Age and timing matter less than people fear. A 22-year-old graduate and a 38-year-old manager can both begin data analytics training for beginners this month, and both can reach interview-ready skill with consistent practice. What decides the outcome is regular effort and the quality of the projects you complete, not where you start.
A sound programme teaches skills in layers, so each tool makes the next one easier. Here is what to expect in data analytics training for beginners.
Excel is usually the first tool an analyst picks up, and it stays useful throughout a career. You will learn data cleaning (removing duplicates, fixing formats, handling blanks), pivot tables that summarise thousands of rows in seconds, lookup formulas such as XLOOKUP and SUMIFS, and simple dashboards with charts and slicers. Many reporting and MIS roles still run on Excel, so do not skip it.
Most company data lives in databases, not spreadsheets. SQL (Structured Query Language) lets you pull exactly the rows and columns you need. You will begin with SELECT, WHERE, GROUP BY and ORDER BY, then move to JOINs for combining tables and, later, subqueries and window functions. SQL reads closer to English than to code, which makes it friendly for beginners.
Power BI and Tableau turn tables into interactive dashboards. You will learn to connect data sources, build measures, choose the right chart and design a dashboard that answers a manager’s question at a glance. The real skill here is storytelling: showing what matters and leaving out what does not.
Python, usually with the pandas library, handles large files, repeats routine reports automatically and supports basic statistical modelling such as correlation and simple regression. R serves a similar purpose and is common in academic and research settings. You do not need to become a software developer, only to write enough code to automate and analyse.
Generative AI tools can now explain formulas, draft SQL queries, suggest chart types and help debug Python errors. For learners this shortens the early struggle considerably. The caution is that AI can produce confident but wrong output, so you must understand the logic well enough to check it. Treat AI as a tutor and reviewer, not a substitute for understanding.
Core tools at a glance
| Tool | Best used for | Difficulty for beginners | Typical first project |
|---|---|---|---|
| Excel | Cleaning, pivot tables, quick reports | Low | Monthly sales summary |
| SQL | Extracting and combining data from databases | Low to medium | Customer orders report |
| Power BI / Tableau | Interactive dashboards and storytelling | Medium | Regional performance dashboard |
| Python / R | Automation, large datasets, statistics | Medium to high | Analysing a public dataset |
| AI assistants | Explaining code, drafting queries, debugging | Low | Getting help writing a SQL query |
In real work these tools form one workflow. A typical task starts with SQL to pull last quarter’s orders from a database, moves to Excel or Python to clean and check the numbers, and ends in Power BI, where the result becomes a dashboard a manager can use. Seeing this chain early helps you understand why each skill matters and why the order of learning matters too.
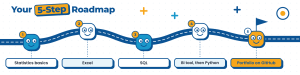
Learning data analytics from scratch is easier with a fixed order. The sequence below suits most beginners.
Spread this over several months and practise a little each day. Steady daily effort beats occasional long sessions. Each step should end with something you can show, not just something you have watched.
Keep a simple log of what you studied and built each week. Reviewing it monthly shows where you are strong and where you keep avoiding a topic. If you are following a structured beginner data analytics course, use the log to prepare questions for your mentor, because specific questions get specific, useful answers.
Courses vary widely in depth and honesty. Use this checklist when comparing options.
Before you enrol in any data analytics training for beginners, put these questions to the institute: Who teaches the sessions and what industry experience do they have? How many projects will I complete, and can I see examples? What happens if I fall behind? Can I speak to a former learner? Straight answers to these tell you more than a brochure does.
Institutes such as Ivy Professional School, which has been training learners since 2008 and counts 37,500+ alumni, structure their beginner pathways around hands-on industry projects and practical portfolio building rather than pure theory. Whichever provider you consider, apply the same checklist and speak to former learners before you commit.
Completing data analytics training for beginners opens several entry-level doors. Common first roles include:
Recruiters for these roles tend to test the same things. They check whether you can write a clean SQL query, summarise a dataset in Excel, explain a dashboard in simple words and reason through a business problem. They also look at your portfolio, because a project you can explain tells them more than a certificate does.
Prepare to talk through at least two projects in detail: the question you asked, the problems in the data, how you solved them and what the business should do next. Clear explanation of your own work is often what separates shortlisted candidates from the rest.
Your first role is a starting point, not a ceiling. With a year or two of experience, analysts commonly move towards senior analyst, data analyst specialist or business intelligence roles, and those who add machine learning skills can later look at data science positions. The foundation you build now, especially in SQL, statistics and clear communication, carries forward into every one of these paths.
Can I learn data analytics without a coding background? Yes. Excel, SQL and BI tools need no prior programming. Python is introduced gradually, and most beginners pick up the basics with regular practice.
How long does data analytics training for beginners take? It varies with your pace and prior knowledge. Most structured programmes run for a few months, and you should expect to keep building your portfolio after the course ends.
Is maths necessary for data analytics? You need school-level maths and a working grasp of basic statistics. Advanced mathematics is not required for entry-level analyst roles.
Which tool should I learn first? Start with Excel, then SQL. Together they cover most entry-level analytics work and are the most common skills tested in interviews.
Can I switch to data analytics from a non-IT job? Yes. Professionals from finance, marketing, operations and commerce move into analytics regularly, and their domain knowledge is a real strength.
Data analytics is a learnable skill, and you can start without a technical background. The path is clear: learn basic statistics, then Excel, SQL, a BI tool and Python, and prove each skill through projects you can explain. Use AI tools to learn faster, but always check their work.
Choose training that gives you mentorship, real projects and honest outcomes, and keep practising after the classes end. Progress will feel slow at first and then speed up as the pieces connect.
If you would like to see how a structured pathway looks, you can explore the beginner-friendly programmes at Ivy Professional School and compare them against the checklist above. Start small, stay consistent and let your portfolio do the talking.
Prateek Agrawal Nov 07, 2026 No Comments
Choosing a data analytics course with placement is one of the most practical career decisions you can make today. Every company, from a neighbourhood retailer to a large bank, now depends on people who can turn raw numbers into clear decisions.
This guide explains what a good data analytics course should teach, how the learning path works, which tools matter, and what to expect on salary and placement. It is written for freshers, working professionals changing careers, and aspiring data analysts.
Quick answer: A strong data analytics course with placement teaches SQL, Python, Power BI and Gen AI through real projects. It then supports you with resume work, mock interviews and introductions to hiring companies.
Data skills are now a basic expectation in sales, finance, HR, marketing and operations. Employers want a data analyst who can query a database, clean messy files and explain the result to a manager.
A course alone does not get you hired. A data analytics course with placement links your learning to hiring, so the skills you build match what companies actually test.
Most job descriptions for a data analyst ask for the same core skills:
If your data analytics course covers these and proves them through projects, you are building the right profile.
This path suits three groups. Each starts from a different point.
If you have just finished a degree in commerce, science, engineering or arts, a data analytics course gives you a job-ready skill set. You do not need a coding background. A good programme starts from the basics and builds up.
Many learners come from sales, operations, finance, HR or teaching. Your domain knowledge is an advantage. A marketing executive who learns SQL and Power BI can often move into a marketing analytics role faster than a fresh graduate.
If you already know some Excel or have tried a few online tutorials, structured training fills the gaps. You get a defined sequence, feedback from trainers and projects you can show in interviews.
Not every data analytics course is built the same way. Use this table to check what you are being offered.
| Component | What it should cover | Why it matters |
| Excel and statistics | Formulas, pivot tables, probability | Builds analytical thinking |
| SQL | Joins, subqueries, window functions | Tested in most analyst interviews |
| Python | pandas, NumPy, Matplotlib | Handles large, messy data |
| Power BI | Power Query, DAX, dashboards | Turns analysis into reports |
| Gen AI | Prompting, LLM tools, tokenization | Speeds up routine analysis |
| Capstone projects | End-to-end business problems | Gives you proof of skill |
| Placement support | Resume, mock interviews, hiring partners | Converts skills into offers |
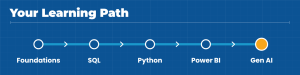
A clear sequence matters more than the number of topics. This learning path works for most beginners.
Start with Excel, basic statistics and the way business data is structured. Learn how to spot errors in a dataset and how to summarise numbers using averages, medians and distributions.
Do not skip this stage. Weak statistics is the most common reason a new data analyst presents a confident chart with a wrong answer.
Move to SQL next, because most business data sits in databases. Learn to filter, group, join and rank data until you can answer a business question without help.
Python comes third, once you think in tables and filters. It lets you handle data that is too large or too messy for Excel.
Now learn to present. Power BI turns your SQL and Python output into dashboards that managers can read in minutes.
The last stage adds Gen AI skills, capstone projects and placement preparation. By now you have enough skill to build something real and explain it clearly.
Tools change, but the thinking behind them stays useful. Here is what you should be able to do with each one.
Python is the main programming language for a modern data analyst. You use it to clean data, run analysis and automate repeat work.
Core libraries to learn:
A typical task is taking a large sales file, removing duplicates, fixing dates and finding which products drive the most profit. If you can do that end to end, you are ready for most entry-level Python questions.
SQL is how you ask a database questions. Almost every data analytics interview includes a SQL round, so this skill carries real weight.
Focus on these areas:
Practise on real tables like orders, customers and products. Interviewers prefer a candidate who writes clean queries over one who memorises syntax.
Power BI is the most common reporting tool in Indian companies. A data analyst uses it to build dashboards that update automatically.
Key skills include:
A good dashboard answers one business question quickly. If your manager needs a long explanation, redesign it.
Gen AI tools now help with writing first-draft SQL and Python, summarising reports and classifying customer feedback. They save time, but they make mistakes.
Learn to check every output against the data. A data analyst who uses Gen AI carefully is faster. One who trusts it blindly is a risk.
Tokenization means splitting text into small units called tokens. A token can be a word, part of a word or a single character.
Language models read and produce tokens, not full sentences. This matters to you for three reasons:
Understanding this helps you build better Gen AI workflows and avoid surprise costs.
Imagine a retail manager asks why sales fell last month. A good analyst does not open a chart first. They start by clarifying the question.
Follow this sequence:
The result is a one-page summary, not a long report. The manager wants to know what happened and what to do next.
Tools get you shortlisted. Judgement gets you hired. Employers look for a few habits that no software teaches.
Know how the company makes money. A number only matters when you can link it to revenue, cost or customer experience.
Explain findings in plain words. Use one chart per point and one sentence per finding.
Ask why a number looks odd before you report it. A careful check catches errors that embarrass analysts later.
Capstone projects separate a certificate from a skill. Recruiters want to see how you handle a full problem, from raw data to a recommendation.
| Project | Business question | Tools | What you deliver |
| Sales and profit dashboard | Which regions and products earn the most? | SQL, Power BI | Interactive dashboard |
| Customer churn analysis | Why are customers leaving? | Python | Findings and a prediction model |
| HR attrition study | Which employees are likely to resign? | Python, Power BI | Report with recommendations |
| Customer feedback analyser | What do customers complain about? | Python, Gen AI, tokenization | Summary of themes |
Put every project in a portfolio with a short write-up. State the problem, the data, your method and the result in plain language.
Add a link to your dashboard or code. A hiring manager should understand your work in two minutes.
Pay depends on your city, your skills, your domain and the company. A data analytics course with placement cannot promise a fixed salary, and you should be careful of any institute that does.
Here is what usually moves the number up:
| Profile | What raises pay | Salary range per year (INR) |
| Fresher data analyst | SQL, Power BI, strong projects | [Insert approved range] |
| Career switcher | Domain knowledge plus data skills | [Insert approved range] |
| Experienced data analyst | Python, Gen AI, business impact | [Insert approved range] |
Ivy Professional School reports a 67% average salary hike for learners who move into new roles after training. Your own result will depend on your starting point and effort.
Your first role is a starting point, not a ceiling. Most learners begin in one of a few common roles and grow from there.
After two or three years, analysts often move into senior analyst, analytics manager or data science roles. The path you pick depends on whether you enjoy people, business strategy or deeper technical work.
Pick a domain early. An analyst who understands retail, banking or healthcare is harder to replace than a generalist.
Placement support should be specific, not a vague promise. Ask any institute exactly what it does for you.
A useful data analytics course with placement includes:
Honest answers to these questions tell you more than any brochure.
Your resume should show what you built, not only what you studied. Lead with projects, name the tools you used and state the result in one line.
Expect three kinds of questions: technical, case-based and behavioural. Technical rounds test your queries and your logic. Case rounds hand you a business problem and ask how you would approach it.
Practise explaining a project aloud. If you cannot describe your own dashboard in two minutes, an interviewer will notice.
Ivy Professional School has trained learners in data skills since 2008. The numbers below are the approved figures for our programmes.
| Measure | Figure |
| Experience | 18+ years (since 2008) |
| Alumni | 37,500+ |
| Trainers | 400+ |
| Hiring companies | 500+ |
| Placement | 82% |
| Average salary hike | 67% |
| Google rating | 4.8/5 from 2,250+ reviews |
| Recognition | Recognized by MeitY |
Classes run across Kolkata, Bangalore, Delhi, Pune and Mumbai, with an online option for learners elsewhere. The data analytics course focuses on SQL, Python, Power BI and Gen AI, with projects at every stage.
Many learners lose months on avoidable errors. Watch for these:
Depth beats breadth. Employers hire people who can finish a task, not people who have seen every tool.
Working professionals have less time but more context. A steady routine works better than occasional long sessions.
Treat your current job as a source of project ideas. A report you build for your own team can become a portfolio piece.
Use this short checklist before you pay any fee:
If the answer to most of these is yes, you are looking at a serious data analytics course with placement.
Learning data skills takes steady effort over several months. Some people get an offer quickly, and others need more projects and more interview practice.
That is normal. Keep building, keep applying and ask for feedback after every interview. Each round teaches you something that the next round will reward.
Track your progress in a simple sheet. Note each application, the interview stage reached and the topics you found hard. After ten interviews, the pattern will show you exactly what to revise.
No. A good programme starts from the basics. Many successful data analysts began with only Excel.
Learn SQL first. It is easier to start with, and it appears in almost every interview.
No course can guarantee a job. A good one improves your skills, your portfolio and your access to hiring companies, and the effort you put in decides the rest.
Data analytics rewards people who practise consistently, week after week, with real datasets. Pick a course that teaches SQL, Python, Power BI and Gen AI through real projects, and supports you all the way to the interview table.
If you are ready to start, speak to an Ivy counsellor and ask for the full syllabus, project list and placement details.
Prateek Agrawal Aug 29, 2026 No Comments
If you have been researching data careers, chances are you have typed “best data engineering course with placement” into Google more than once. That is a good instinct, data engineering has quietly become one of the highest-paying, most stable roles in the Indian tech industry, and picking the right program can make or break how quickly you land your first job in the field. In this guide, we will break down exactly what to look for, what a strong curriculum should include, and how a placement-focused program can take you from beginner to hired data engineer.
Data engineers build and maintain the pipelines, warehouses, and infrastructure that allow organizations to collect, clean, and use data at scale. Every dashboard a business analyst opens, every machine learning model a data scientist trains, and every recommendation engine an e-commerce site runs depends on a data engineer having built reliable systems behind the scenes.
As Indian companies — from fintech startups to global capability centers — accelerate their adoption of cloud computing, real-time analytics, and generative AI, the demand for skilled data engineers has surged well beyond the supply of qualified professionals. Job portals consistently list data engineering among the fastest-growing tech roles, and salaries have risen accordingly. This gap between demand and skilled supply is precisely why so many career switchers and freshers are now searching for the best data engineering course with placement rather than trying to piece together skills through scattered YouTube tutorials.
The catch is that data engineering is not a “watch a few videos and you’re job-ready” kind of field. It requires structured learning across programming, databases, distributed systems, cloud platforms, and orchestration tools — which is exactly why a well-designed, mentor-led course with genuine placement support matters so much.
Not every course that advertises “placement assistance” delivers on it. Before enrolling, evaluate a program against these criteria:
When you filter your shortlist using these six criteria, you naturally narrow down to programs that can genuinely call themselves the best data engineering course with placement — as opposed to marketing copy dressed up as a guarantee.
A placement-ready data engineering curriculum should be built in layers, moving from fundamentals to production-grade systems:
A course missing several of these layers is unlikely to prepare you for real interviews, regardless of how it markets itself. This is the benchmark to hold any program to when you’re comparing options for the best data engineering course with placement.
At Ivy Pro School, the data engineering program is designed around exactly the curriculum layers above, taught by practitioners rather than purely academic instructors. A few things set the program apart:
Combine institutional pedigree with a genuine placement engine, and you get a program that doesn’t just teach data engineering concepts — it engineers outcomes. That combination of curriculum depth, mentorship, and accountability is what makes this the best data engineering course with placement for learners who are serious about breaking into the field, whether they’re fresh graduates or working professionals pivoting from adjacent roles like software development, QA, or business analytics.
The phrase “placement assistance” gets used loosely across the ed-tech industry, so it’s worth understanding what genuine placement support actually looks like:
This is the layer that separates a course from a career transition. Plenty of programs teach Spark and Airflow reasonably well; far fewer put in the structural work to get you hired afterward. Spend as much time scrutinizing this section of a program as you do the technical syllabus, since it is usually the deciding factor between a completed certificate and an actual job offer.
Even motivated learners waste months and money by making avoidable mistakes during the selection process:
Avoiding these pitfalls up front saves both time and tuition, and it usually points you straight toward programs with a genuine track record of outcomes rather than marketing promises.
Data engineering offers several career trajectories once you have foundational skills in place:
Salaries in this field have grown steadily as demand has outpaced the supply of trained professionals, with entry-level data engineers in India commanding competitive packages compared to many other tech roles, and experienced engineers with cloud and big data expertise commanding significantly higher compensation. This growth trajectory is a major reason so many professionals are actively pursuing structured training instead of relying on self-study alone — the field rewards demonstrable, hands-on expertise, and employers pay a premium for candidates who can prove it through real pipeline projects and credible certification rather than a list of watched tutorials.
Beyond base salary, data engineers often see faster promotion cycles than adjacent roles, since the skill set transfers directly into senior positions like data architect, platform lead, or engineering manager for data infrastructure teams. Companies also increasingly value data engineers who understand the basics of machine learning workflows, since MLOps and AI infrastructure roles are growing out of traditional data engineering teams as generative AI adoption accelerates across industries.
Both formats can lead to the same outcome, but they suit different learners:
Classroom or hybrid learning works well if you value in-person mentorship, peer accountability, and a structured daily routine — which is why Ivy Pro School maintains physical centers in Kolkata, Bangalore, and Delhi alongside its online offering.
Live online learning works well for working professionals who need flexibility around existing job commitments but still want real-time instructor interaction rather than pre-recorded, self-paced content.
What matters more than the format is whether the program includes live doubt-clearing sessions, project reviews, and direct placement support — self-paced, pre-recorded courses with no human accountability structure rarely deliver strong placement outcomes, regardless of how comprehensive the video library looks on paper.
Recruiters screening resumes for data engineering roles tend to look for a specific, recognizable toolkit, and a strong course should give you working proficiency — not just theoretical familiarity — across most of the following:
A program that only teaches two or three items from this list will leave graduates under-prepared for technical interviews, where hiring managers routinely test candidates on how these tools interact rather than testing each one in isolation. This is also why capstone projects matter so much — they force learners to combine several of these tools into a single working pipeline, which is a far closer approximation of real job responsibilities than isolated exercises ever could be.
Q: How long does it take to complete a data engineering course with placement? Most structured programs run between 6 and 9 months, depending on whether you’re studying full-time or alongside a job, with placement support typically continuing for several months after course completion.
Q: Do I need a coding background to enroll? No. A good program builds programming and SQL skills from the ground up, though basic logical reasoning and comfort with computers will help you move faster through the early modules.
Q: Is data engineering harder to break into than data science? Not necessarily — it’s a different skill set, more focused on systems, pipelines, and infrastructure than statistics and modeling. Many learners find the more engineering-oriented, less mathematically heavy curriculum easier to grasp.
Q: What makes Pay After Placement different from a regular fee structure? It shifts financial risk away from the learner and ties the institute’s revenue directly to your getting placed, which tends to correlate with stronger, more hands-on placement support.
Q: Can working professionals switch careers into data engineering? Yes — professionals from software development, QA, database administration, and even business analytics backgrounds frequently transition into data engineering roles, often bringing relevant domain knowledge that strengthens their candidacy.
Q: Which cloud platform should I learn first for data engineering? Most learners start with AWS, since it has the largest market share in India’s hiring landscape, though a strong program will expose you to the core concepts of Azure and GCP as well, since many enterprises run multi-cloud environments.
Q: Does Ivy Pro School offer both classroom and online batches for data engineering? Yes — the program runs at physical centers in Kolkata, Bangalore, and Delhi, alongside live online batches for learners who need remote flexibility while keeping real-time instructor interaction and doubt-clearing support.
Choosing the best data engineering course with placement comes down to three things: a curriculum that genuinely covers the tools employers use, instructors who have worked with those tools in production, and a placement system that goes far beyond a vague promise in the brochure. Ivy Pro School’s data engineering program combines all three — an 18-year institutional track record, NASSCOM and IBM industry partnerships, and a Pay After Placement model designed to keep the institute accountable for your outcome, not just your attendance.
If you’re serious about building a career in data engineering, it’s worth attending a free career counseling session at Ivy Pro School’s Kolkata, Bangalore, or Delhi centers, or joining a live online orientation, to see the curriculum, meet instructors, and understand exactly how the placement process works before you commit.
Prateek Agrawal Jul 11, 2026 No Comments
Every digital business depends on reliable data. Customer transactions, website events, financial records, application logs and sensor readings must be collected, cleaned, organised and delivered to the people and systems that need them. Data engineers build the infrastructure that makes this possible.
A strong data engineering skillset goes beyond knowing a programming language or operating a cloud tool. It combines database knowledge, software engineering, data architecture, distributed processing, security, problem-solving and business understanding.
This guide explains the core data engineer skills employers expect, the tools associated with each skill and a practical roadmap for developing job-ready capability.
A data engineering skillset is the combination of technical, analytical and professional abilities required to design, build, operate and improve data systems.
A data engineer may extract data from databases, APIs and applications; transform raw data into consistent datasets; build batch and streaming pipelines; design warehouses and lakes; maintain data quality; and support analytics, machine learning and AI applications.
| Skill area | What you should know | Common tools |
| SQL | Queries, joins, windows and optimisation | PostgreSQL, MySQL, SQL Server |
| Programming | Automation, APIs, transformation and testing | Python, Java, Scala |
| Data modelling | Schemas, facts, dimensions and normalisation | dbt, modelling tools |
| Pipelines | ETL, ELT, retries and incremental loading | Airflow, ADF, AWS Glue |
| Distributed processing | Large-scale data processing | Spark, Databricks |
| Streaming | Events, producers, consumers and offsets | Kafka, Kinesis |
| Cloud | Storage, compute, identity and cost control | AWS, Azure, Google Cloud |
| Quality and governance | Testing, lineage and access control | Great Expectations, Purview |
| DevOps | Version control and automated deployment | Git, Docker, CI/CD tools |
| Business skills | Requirements, documentation and communication | Jira, Confluence |
SQL is the foundation of the data engineering skillset. Engineers use it to inspect source systems, transform data, validate results, create warehouse models and troubleshoot pipeline failures.
A job-ready professional should be comfortable with joins, common table expressions, subqueries, aggregate functions, window functions, date and string functions, deduplication, views, stored procedures, indexes, partitions and query execution plans.
Returning the correct result is only the first step. A data engineer must also consider how a query performs when a table contains millions of records. This requires knowledge of filtering, indexing, partition pruning, data distribution and unnecessary data movement.
Python is commonly used for data ingestion, transformation, API integration, automation and testing. Its standard data structures and extensive ecosystem make it practical for reusable data workflows.
Important skills include:
Libraries such as pandas are useful for moderate-sized data, while PySpark supports distributed processing. Python should be learned through practical tasks such as extracting paginated API data, validating schemas, processing files and loading results into databases.
Pipelines create value only when their outputs are structured for business use. Data modelling is therefore a core part of the data engineering skillset.
Engineers should understand:
Operational databases are designed for frequent inserts and updates. Analytical systems are designed for large scans, aggregations and historical analysis. Recognising this difference helps engineers build models that are both accurate and efficient.
Modern frameworks such as dbt allow teams to create modular SQL models and combine them with testing, documentation, lineage and version-controlled workflows.
ETL means extract, transform and load. ELT means extract, load and transform. Both patterns move data from source systems into analytical platforms.
A capable data engineer should know how to:
Reliable pipelines should be idempotent, meaning they can be rerun safely without creating duplicates or corrupting results. They should also account for late files, network failures, API rate limits and changing source schemas.
A complete data engineering skillset includes the major patterns used to store analytical data.
A data warehouse stores curated data optimised for reporting and analysis. Common examples include Snowflake, Google BigQuery, Amazon Redshift and Azure-based warehouse services.
A data lake stores large volumes of structured, semi-structured and unstructured data, typically in object storage.
A lakehouse combines the flexibility of data-lake storage with warehouse-style performance, management and governance.
Important storage concepts include:
The objective is not to memorise every product interface. It is to understand why a storage pattern suits a workload and what trade-offs it creates in performance, governance and cost.
When data becomes too large or processing too complex for one machine, distributed computing becomes necessary. Apache Spark is widely used for data engineering, data science and machine learning workloads.
A practical Spark skillset includes:
Many beginners focus only on PySpark syntax. Employers need engineers who can diagnose why a job is slow, why a join creates excessive shuffling or why thousands of small files reduce performance.
Batch pipelines process data at scheduled intervals. Streaming systems process events continuously or in short windows.
Apache Kafka is a distributed event-streaming platform used to publish, retain and process streams of events.
Engineers working with streaming data should understand:
Managed alternatives include Amazon Kinesis and Azure Event Hubs. AWS describes Kinesis as a service for collecting, processing and analysing real-time streaming data.
A practical streaming project could process e-commerce clickstream events, calculate rolling product views and store the resulting metrics for a dashboard.
Production data platforms contain dependent tasks that must run in the correct order. Orchestration tools schedule these tasks, manage dependencies and monitor their status.
Apache Airflow is designed for developing, scheduling and monitoring batch-oriented workflows, typically represented as directed acyclic graphs or DAGs.
Relevant orchestration skills include:
Other options include Azure Data Factory, Google Cloud Composer, Databricks Workflows and Microsoft Fabric Data Factory.
The core skill is understanding how workflows behave when tasks fail, data arrives late or historical periods must be reprocessed.
Most modern data engineering roles require exposure to at least one major cloud platform: Microsoft Azure, Amazon Web Services or Google Cloud.
A cloud-ready data engineering skillset should cover:
AWS, for example, provides analytics services across querying, processing, governance, warehousing and streaming, including Athena, EMR, Glue, Redshift, Lake Formation and Kinesis. Azure and Google Cloud offer comparable capability categories under different service names.
Beginners should not attempt to master all three clouds simultaneously. Choose one ecosystem, build an end-to-end project and then map the concepts to equivalent services elsewhere.
A pipeline is not successful merely because it finishes without an error. It must deliver accurate, complete, timely and trustworthy data.
Engineers should create checks for:
Testing operates at several levels. Unit tests validate code components. Integration tests confirm that systems work together. Data tests verify the properties of output datasets.
Observability extends this approach by monitoring pipeline duration, failure rates, data freshness, volume changes, lineage and downstream impact.
Engineers must also decide what happens when a check fails. Depending on the level of risk, the pipeline may stop, quarantine records, issue a warning or continue with an audit flag.
Data engineering is a software engineering discipline. Production pipelines should not depend on manually edited scripts stored on individual computers.
Core engineering practices include:
dbt explicitly applies software engineering practices such as version control, modularity, testing, CI/CD and documentation to data transformation workflows.
Data engineers frequently work with financial, customer, employee and operational data. Security must be built into the system.
Relevant skills include:
Governance ensures users understand where data came from, what it means, who owns it and who may access it. A catalogue, business glossary and lineage system make data easier to discover while reducing misuse.
Engineers do not need to act as legal experts, but they must translate security and governance requirements into technical controls.
Technical skill alone does not create useful data products. Data engineers must understand the business meaning behind the requested data.
If a stakeholder asks for “daily sales data,” the engineer must clarify:
Useful professional skills include requirement gathering, documentation, estimation, prioritisation, stakeholder communication and incident reporting.
Engineers should be able to explain technical trade-offs in terms of reliability, time, risk and cost.
AI coding assistants can generate SQL, explain unfamiliar code, create documentation and accelerate troubleshooting. Data platforms are also adding AI-supported development features.
dbt, for example, documents AI capabilities grounded in project context such as lineage, tests, contracts and metric definitions.
However, generated code may be inefficient or apply incorrect business logic. Suggested configurations may also create security, performance or cost issues.
The emerging skill is not simply using AI. It is using AI with sufficient context, review, testing and governance. Engineers who understand the fundamentals can use these tools to move faster without sacrificing reliability.
Beginners do not need to master every technology before applying for roles. A practical sequence is:
This sequence develops depth before breadth. It is more effective than gaining superficial exposure to dozens of tools.
Experienced professionals should move beyond tool operation towards architecture, platform reliability, cost optimisation, governance, reusable components and technical leadership.
A portfolio should demonstrate complete workflows and engineering decisions.
Extract order and customer data from an API, store raw files in object storage, transform the data, load warehouse tables and produce daily sales metrics.
Generate website events, publish them to a streaming platform, calculate windowed metrics and store the results for analysis.
Create configurable checks for duplicates, nulls, row counts, freshness and source-to-target totals. Produce an audit report after every pipeline run.
Build a dimensional model, implement incremental loading, add role-based access and document cost-optimisation decisions.
Each project should contain a README, architecture diagram, data model, source code, tests, sample outputs and deployment instructions. Explain trade-offs and limitations instead of presenting the work as flawless.
Common mistakes when building data engineer skills include:
A balanced data engineering skillset combines conceptual depth, implementation ability and operational discipline.
The most important skills are SQL, Python, data modelling, ETL or ELT, databases, cloud platforms, orchestration, data quality, Git and communication. Spark and streaming tools become important for large-scale or real-time systems.
No. Python is valuable, but data engineering also requires SQL, database concepts, modelling, pipeline design, cloud services, testing and operational skills.
Deep machine learning expertise is not mandatory for most roles. However, understanding model-training data, feature pipelines and production inference helps when supporting AI and machine learning teams.
Azure, AWS and Google Cloud all support enterprise data engineering. The best starting platform depends on your target employers, existing experience and technology environment. Learn one platform deeply before covering all three.
Yes. Entry-level candidates should focus on SQL, Python, databases, ETL, Git and one cloud ecosystem, then demonstrate these skills through complete projects.
The timeline depends on prior programming and database experience. Readiness is better measured by whether you can independently design, build, test, explain and troubleshoot an end-to-end pipeline.
The ideal data engineering skillset is not a checklist of fashionable tools. It is the ability to build data systems that are accurate, scalable, secure, maintainable and useful to the business.
Start with SQL, Python, databases and data modelling. Progress to pipelines, cloud platforms, orchestration, distributed processing, data quality and governance. Reinforce each stage with practical projects and professional engineering practices.
As organisations expand analytics, machine learning and enterprise AI, reliable data engineering becomes increasingly valuable. Professionals who combine technical depth with business understanding will be better positioned to build the trusted data foundation these systems require.
To develop these capabilities through structured training and hands-on projects, explore the Data Engineering Programme at Ivy Professional School.
Prateek Agrawal Jun 27, 2026 No Comments
The average data engineering salary in India is approximately ₹10 lakh per year. However, actual salaries can range from around ₹4 lakh per year for freshers to more than ₹40 lakh per year for experienced data engineers, data architects and engineering leaders.
The data engineering salary offered by an organisation depends on several factors, including the candidate’s experience, technical skills, educational background, industry, location and ability to work with modern cloud-based data platforms.
A professional who knows basic SQL and Python may start with a moderate package. In comparison, someone who can build scalable cloud pipelines, manage distributed data-processing systems and design enterprise data platforms can command a substantially higher data engineering salary.
| Experience Level | Indicative Annual Salary |
| Fresher or entry-level professional | ₹4–8 lakh |
| 2–4 years of experience | ₹7–14 lakh |
| 5–8 years of experience | ₹14–25 lakh |
| 8 or more years of experience | ₹22–40 lakh or more |
| Data architect or engineering leader | ₹30–60 lakh or more |
These figures are broad market estimates. Product companies, global capability centres, fintech organisations and high-growth technology companies may offer compensation above these ranges.
The data engineering salary is increasing because companies are generating more data than ever before.
Businesses collect information through websites, mobile applications, customer transactions, enterprise resource planning systems, marketing platforms, connected equipment and social media channels. This data must be collected, cleaned, integrated, stored and made available before it can support business decisions.
Data engineers build the infrastructure that makes this possible.
Their work supports:
Organisations may employ data analysts and data scientists, but these professionals cannot work effectively without reliable data pipelines. This dependency has increased the importance of data engineers and contributed to the growth of the data engineering salary across industries.
Data engineering also requires a combination of skills that is not always easy to find. Employers need professionals who understand programming, databases, cloud infrastructure, distributed computing, security, governance and business requirements.
This combination of technical depth and operational responsibility makes data engineering one of the better-paid career options within the broader data and analytics domain.
The typical data engineering salary for freshers in India ranges from approximately ₹4 lakh to ₹8 lakh per year.
Candidates from recognised engineering institutions, applicants with relevant internships and professionals who have completed practical cloud projects may receive higher offers. Some premium product companies and global technology organisations may offer entry-level packages above ₹10 lakh per year.
A fresher’s starting package depends on several important factors.
SQL is one of the most important skills for an entry-level data engineer. Candidates should be comfortable with:
Freshers who can solve realistic business problems using SQL may qualify for a better data engineering salary than candidates who know only basic commands.
Python is widely used for pipeline development, data transformation, automation, validation and API integration. Knowledge of Java or Scala may also be valuable, particularly in organisations using Apache Spark.
A candidate does not need to be an advanced software engineer at the beginning of the career. However, the ability to write clean, reusable and well-structured code can improve employment opportunities.
Completing online courses is useful, but employers increasingly look for practical evidence of capability.
A strong beginner-level project may involve:
Candidates who can explain the complete architecture of such a project may negotiate a stronger data engineering salary.
Entry-level professionals should develop practical familiarity with at least one cloud platform:
Even basic experience with cloud storage, pipeline orchestration and data warehouses can strengthen a fresher’s profile.
An internship involving SQL, Python, cloud platforms, business intelligence or backend development can improve employability. It demonstrates that the candidate understands how data systems work in a professional environment.
Freshers should not evaluate a role only by its initial compensation. A lower-paying position that provides exposure to Spark, Databricks, Snowflake or Azure Data Factory may create better long-term growth than a higher-paying role restricted to repetitive manual tasks.
Experience is one of the biggest determinants of compensation. However, the quality and relevance of the experience are more important than the number of years alone.
The data engineering salary for an entry-level professional generally ranges from ₹4 lakh to ₹9 lakh per year.
Common responsibilities include:
At this stage, professionals should focus on building strong foundations in SQL, Python, data warehousing and cloud technologies.
The data engineering salary for a mid-level professional generally ranges from ₹8 lakh to ₹18 lakh per year.
Mid-level engineers are expected to work independently and take responsibility for complete workflows. Their responsibilities may include:
Professionals who can work with Spark, Databricks, Kafka, Snowflake or modern cloud services are often positioned toward the upper end of the salary range.
The data engineering salary for a senior professional typically ranges from ₹15 lakh to ₹30 lakh per year.
Senior data engineers are expected to make architecture decisions, manage technical risks and guide junior team members.
Their responsibilities frequently include:
At this level, communication, system design and stakeholder-management skills become as important as coding ability.
Lead data engineers, engineering managers and data architects may earn between ₹25 lakh and ₹50 lakh per year. Professionals working for premium global companies may receive even higher compensation.
At this level, the data engineering salary may include fixed pay, performance bonuses, stock options and retention incentives.
These professionals may be responsible for:
Location continues to influence salaries, although remote and hybrid roles have reduced some geographical differences.
Bengaluru generally offers some of the highest salaries in India because of its concentration of technology companies, global capability centres and startups.
The data engineering salary in Bengaluru may range from ₹7 lakh to ₹30 lakh per year, depending on experience and specialisation. Senior professionals working for product companies may earn substantially more.
Hyderabad has a strong presence of multinational technology companies, pharmaceutical organisations, financial-services firms and cloud development centres.
Data engineers in Hyderabad may earn approximately ₹6 lakh to ₹25 lakh per year.
Pune offers opportunities across IT services, automotive, manufacturing, banking and enterprise software.
The data engineering salary in Pune may range from approximately ₹5.5 lakh to ₹22 lakh per year.
Mumbai’s banking, fintech, consulting, insurance and media sectors create demand for professionals who can handle large and sensitive datasets.
Salaries may range from ₹6 lakh to ₹25 lakh per year, with premium opportunities available in banking and fintech.
Gurugram and Noida host consulting companies, ecommerce organisations, global capability centres and technology firms.
The data engineering salary in Delhi NCR may range from ₹6 lakh to ₹26 lakh per year.
Chennai offers data engineering opportunities in IT services, automotive, manufacturing, banking and software development.
Professionals may earn between ₹5 lakh and ₹22 lakh per year.
Data engineering opportunities in Kolkata are expanding across analytics, consulting, IT services and remote engineering teams.
While the local data engineering salary may sometimes be lower than salaries in Bengaluru or Gurugram, remote employment is giving professionals access to national and international opportunities.
Candidates should compare compensation with the cost of living, project quality, learning opportunities, work flexibility and long-term career potential.
A degree may help someone enter the profession, but long-term salary growth depends primarily on skills and business impact.
Data engineers must do more than retrieve information from tables. High-paying positions require the ability to:
Advanced SQL capability can directly influence the data engineering salary offered to a candidate.
Python is commonly used for pipeline development, automation, validation and API integration.
Java and Scala are particularly useful in large-scale Spark environments. Professionals who can write tested, maintainable and production-ready code generally earn more than those who depend entirely on visual or low-code tools.
Cloud capability is one of the strongest salary differentiators.
Valuable services include:
Developing deep expertise in one cloud environment can substantially improve a professional’s data engineering salary.
Apache Spark is used to process large datasets across distributed computing environments. Databricks provides a unified platform for data engineering, analytics and machine learning.
Engineers who can optimise Spark jobs, manage clusters and build lakehouse solutions are often eligible for premium compensation.
Employers value professionals who understand:
Knowledge of Snowflake, BigQuery, Redshift, Synapse or Microsoft Fabric can improve the data engineering salary available to a candidate.
Data pipelines must be scheduled, monitored and managed reliably.
Common orchestration tools include:
Professionals who understand dependencies, retries, alerts, logging and failure-handling mechanisms are particularly valuable in production environments.
Real-time data-processing skills can command premium salaries because streaming architectures are technically complex and often business-critical.
Relevant technologies include:
These systems are used in fraud detection, ecommerce personalisation, financial trading, connected manufacturing and operational monitoring.
Modern data engineers increasingly work with:
Data engineers who can deploy, test and monitor pipelines systematically may receive a higher data engineering salary.
Generative AI is increasing the demand for professionals who can build data pipelines for:
Data engineers do not necessarily need to become data scientists. However, understanding how data is prepared and delivered to artificial intelligence applications can create access to premium positions.
Some industries pay more because their data environments are larger, more regulated or closely connected to revenue generation.
| Industry | Salary Potential | Common Use Cases |
| Product technology | High | Customer platforms, AI and large-scale analytics |
| Banking and fintech | High | Transactions, fraud, risk and compliance |
| Ecommerce | High | Recommendations, pricing and customer behaviour |
| Consulting | Medium to high | Cloud migration and client implementations |
| Healthcare | Medium to high | Clinical, operational and compliance data |
| Manufacturing | Medium to high | IoT, production, quality and supply chains |
| IT services | Medium | Enterprise projects and managed services |
| Retail and FMCG | Medium to high | Sales, inventory and consumer analytics |
| Telecommunications | High | Network, customer and streaming data |
The data engineering salary within an industry also depends on the organisation’s technology maturity and the importance of data to its business model.
For example, a traditional manufacturing company beginning its cloud journey may offer different responsibilities and compensation from a digitally mature ecommerce company processing millions of transactions every day.
Data engineers generally earn more than data analysts because engineering roles require deeper programming, infrastructure and system-design capabilities.
| Role | Main Responsibility | Indicative Salary |
| Data analyst | Analyses data and creates reports | ₹4–12 lakh |
| BI developer | Builds dashboards and reporting models | ₹5–15 lakh |
| Data engineer | Builds data pipelines and platforms | ₹6–25 lakh |
| Data scientist | Develops analytical and ML models | ₹7–25 lakh |
| Data architect | Designs enterprise data systems | ₹20–50 lakh or more |
The difference between a data analyst’s compensation and a data engineering salary is not fixed. Senior analysts with strong domain expertise may earn more than junior engineers.
A data analyst can transition into data engineering by developing:
Similarly, backend developers and database professionals can move into data engineering by learning modern data architectures and cloud services.
Data engineering is also a well-paid profession internationally.
In the United States, experienced professionals may earn more than $130,000 annually. Compensation can be significantly higher in product companies when bonuses and equity are included.
In the United Kingdom, salaries may range from approximately £45,000 to £90,000, depending on experience, location and industry.
The data engineering salary in Canada, Australia, Singapore, the Middle East and Europe varies according to market demand, taxation, visa status and the type of organisation.
Professionals comparing international salaries should consider:
A larger salary figure does not automatically result in greater savings or a better quality of life.
Professionals seeking better compensation should follow a deliberate career-development strategy.
Create projects that demonstrate complete data workflows rather than isolated exercises.
A strong portfolio project should include:
Employers value candidates who can explain why they selected a particular architecture and how they handled performance, reliability and security.
Choose Azure, AWS or Google Cloud and become confident with its main data services.
Avoid learning only the names of many tools without being able to implement a working solution. Practical depth is more likely to improve your data engineering salary than superficial exposure to multiple platforms.
Senior roles require an understanding of scalability, reliability, security, performance and cost.
Professionals should be able to explain:
During interviews and performance appraisals, explain measurable outcomes rather than listing routine responsibilities.
Instead of saying:
“I developed ETL pipelines.”
Say:
“I redesigned 15 ETL pipelines, reduced processing time by 40% and lowered monthly cloud costs by 18%.”
Evidence of measurable impact provides stronger justification for a higher data engineering salary.
Senior engineers work with business leaders, analysts, data scientists, security professionals and application-development teams.
The ability to clarify requirements, document decisions and explain technical trade-offs supports promotion into leadership positions.
Changing jobs can produce a larger salary increase than an annual appraisal. However, frequent movement without meaningful skill development may weaken a professional profile.
The best opportunities usually offer a combination of:
Data engineering remains a strong career option because reliable data infrastructure is essential for analytics, automation and artificial intelligence.
AI coding tools may automate some routine SQL generation, documentation and pipeline-development tasks. However, companies still need professionals who can design architecture, validate information, manage security, optimise costs and maintain production reliability.
The data engineering salary is likely to remain attractive for professionals who combine:
Entry-level work may become more automated, making practical experience increasingly important. Candidates who rely only on certificates or memorised interview answers may find it difficult to qualify for high-paying positions.
The average data engineering salary in India is approximately ₹10 lakh per year. Actual salaries vary depending on experience, technical expertise, employer, industry and location.
Freshers can generally expect between ₹4 lakh and ₹8 lakh per year. Candidates with internships, cloud certifications and strong projects may receive higher offers.
Yes. Professionals with approximately four to eight years of relevant experience and expertise in cloud platforms, Spark, Databricks, Snowflake or real-time systems can earn ₹20 lakh or more.
There is no single highest-paying skill. A combination of cloud architecture, Spark, Databricks, data modelling, streaming systems and software-engineering capability generally creates the strongest earning potential.
The average data engineering salary is generally higher than an average data analyst salary because data engineering requires deeper programming and infrastructure knowledge. However, compensation depends on experience, specialisation and business impact.
Yes. Most professional positions require SQL and at least one programming language, commonly Python, Java or Scala. Low-code platforms may support development, but coding ability creates better long-term career flexibility.
Yes. Employers primarily evaluate technical capability, project experience and problem-solving skills. Candidates from non-technical backgrounds may need additional preparation in programming, databases, operating systems and cloud technologies.
Azure, AWS and Google Cloud all offer strong career opportunities. The best option depends on the candidate’s target industries and employers.
AI may automate repetitive development activities, but it is also increasing the need for reliable data platforms. Professionals who use AI tools effectively and develop architecture, governance and engineering skills are likely to remain valuable.
The data engineering salary in India reflects the growing importance of reliable data infrastructure. Freshers may begin with ₹4–8 lakh per year, while experienced engineers, architects and platform leaders can earn ₹25–50 lakh or more.
The strongest salary growth comes from combining advanced SQL, programming, cloud platforms, distributed processing, data modelling and system-design expertise.
Data engineering should not be treated as a collection of tools. It is an engineering discipline focused on creating secure, reliable and scalable systems that make data usable.
Professionals who can solve complex business problems, manage production platforms and support AI-driven applications will continue to command a premium data engineering salary in India and international markets.
Prateek Agrawal May 30, 2026 No Comments
If you are a fresh graduate wondering where to begin, enrolling in a data science course for freshers 2026 could be the single most impactful career decision you make this year. India’s data economy is expanding at an extraordinary pace, and employers across Bangalore, Hyderabad, Pune, and Mumbai are actively hunting for entry-level talent who can work with data confidently. The right data science course for freshers 2026 will equip you with Python, machine learning, SQL, and cloud skills that today’s recruiters actually demand. This guide walks you through everything you need to know: what to learn, where to learn it, how much you can earn, and what the job market truly looks like this year.
The Indian data analytics market was valued at over ₹84,000 crore in 2024 and is projected to cross ₹2,00,000 crore by 2028. Behind those numbers are millions of job roles, data analysts, machine learning engineers, business intelligence developers, data engineers, and AI specialists, many of which remain unfilled because the supply of trained professionals simply cannot keep up with demand. This is precisely why a data science course for freshers 2026 has become one of the most searched career-launch decisions among Indian graduates today.
What changed between 2022 and 2026? Three significant things:
Generative AI has become mainstream. Every company, from a Tier-2 SaaS startup to a large public-sector bank, now needs professionals who understand both traditional data pipelines and large language model (LLM) integrations. Any data science course for freshers in 2026 that does not cover generative AI fundamentals is already outdated. Entry-level candidates who know how to work alongside AI tools are considered far more hireable than those who do not.
The cloud-first economy has deepened. AWS, Google Cloud, and Microsoft Azure are now foundational infrastructure for most Indian businesses. A data science course for freshers 2026 should include at least a module on cloud-based data storage, processing, and model deployment to remain industry-relevant.
Tier-2 cities have opened up. Remote and hybrid work has democratised opportunity. Companies are now hiring data professionals from Jaipur, Coimbatore, Nagpur, and Bhopal, not just the traditional tech metros. This means a fresher anywhere in India can access the same quality of roles as someone sitting in Bengaluru, provided their skills are sharp.
A well-structured data science course for freshers 2026 is not the same as it was even three years ago. The curriculum has evolved significantly to reflect new tools, new employer expectations, and new technologies. Here is what a modern, industry-aligned programme should include:
Python remains the dominant language in data science, and for good reason it is versatile, readable, and supported by an enormous ecosystem of libraries. A good data science course for freshers 2026 will start you with Python basics, data types, loops, functions, file handling, before moving into data-specific libraries:
SQL is equally non-negotiable. Almost every real-world data role requires writing queries to extract and transform data from relational databases. Look for a data science course for freshers 2026 that spends at least 20–30 dedicated hours on SQL, covering joins, subqueries, window functions, and query optimisation.
One of the biggest mistakes freshers make is skipping the mathematical foundations in favour of jumping straight to model-building. Statistics forms the backbone of every machine learning technique, and the best data science course for freshers 2026 will make sure you understand it deeply. A solid programme covers:
You do not need to be a mathematician, but you do need enough statistical intuition to interpret results correctly and avoid common modelling pitfalls.
This is the core of most programmes. A complete data science course for freshers 2026 should cover both supervised and unsupervised learning:
In 2026, a competitive data science course for freshers will also introduce deep learning fundamentals — neural networks, CNNs, and RNNs — along with an introduction to transformer architectures, which underpin most modern AI systems.
Raw data is almost always messy. A significant portion of a practising data scientist’s time goes into cleaning, transforming, and understanding data before any model is built. The best data science course for freshers 2026 simulates this reality with messy, real-world datasets rather than polished toy examples, so you are prepared for what actual work looks like.
Being able to build a model is only half the job. Communicating findings to non-technical stakeholders such as product managers, business heads, CFOs is equally important. A strong data science course for freshers 2026 will include tools like:
Modern data science does not end at a Jupyter notebook. Freshers are now expected to understand how models get deployed and maintained in production. A forward-looking data science course for freshers 2026 should introduce:
This is the newest — and most exciting — addition to entry-level curricula. Understanding how to use APIs like OpenAI or Claude, build simple RAG (Retrieval Augmented Generation) pipelines, and work with vector databases is fast becoming a standard expectation. Any data science course for freshers 2026 worth your money will include at least an introductory module on generative AI tools and workflows.
With hundreds of options available, from 12-week bootcamps to two-year postgraduate programmes — choosing the right data science course for freshers 2026 is critical. Here are the factors that should guide your decision:
Check when the syllabus was last updated. A data science course for freshers designed in 2021 will not cover generative AI, modern MLOps tools, or the latest industry frameworks. Ask the provider directly or look for syllabi published on their website. If the course still treats deep learning as “advanced optional content,” move on.
Recruiters in India’s data science market care far more about your portfolio than your certificates. A strong data science course for freshers 2026 should include at least 3–5 end-to-end projects on real datasets — ideally across different domains such as finance, healthcare, e-commerce, and logistics.
Look for programmes that offer live sessions with industry practitioners, code reviews, and dedicated placement assistance. Mock interviews, resume workshops, and access to hiring networks significantly increase your chances of landing your first role after completing a data science course for freshers 2026.
For freshers with no prior background, a programme of 6–12 months is typically necessary to build genuine proficiency. Shorter crash courses may introduce concepts but rarely produce job-ready candidates. When evaluating a data science course for freshers 2026, ask providers for placement statistics — specifically median time-to-hire and average starting salary — before enrolling.
Reputable programmes in India range from ₹30,000 for self-paced online courses to ₹3,00,000 or more for full-time immersive bootcamps with placement guarantees. Many platforms offering a data science course for freshers 2026 also provide EMI options, income-share agreements, or merit-based scholarships.
Understanding the landscape before you enter it saves time and helps you target the right roles.
Bengaluru leads as India’s data science hub, but Hyderabad, Pune, Chennai, and the NCR (Noida and Gurugram) are all strong markets. In 2026, remote-first roles are especially common in product companies and global capability centres (GCCs), giving freshers outside metros genuine opportunities without relocating — provided they have completed a solid data science course for freshers 2026 that prepared them for independent work.
A certificate alone will not get you an interview. What matters is proof that you can apply your skills to real problems. The best data science course for freshers 2026 will help you build this portfolio as part of the programme, but here is how to go further:
Every project should be uploaded to GitHub with a clear README explaining the business problem, methodology, key findings, and model performance metrics. Kaggle competitions are an excellent way to benchmark your skills — even a top-50% finish on a public competition demonstrates that you can work with messy, real data under defined objectives.
Writing about what you learn — a tutorial, a case study, a model explainer — signals communication skills and genuine intellectual curiosity. A consistent LinkedIn presence showing your projects, learnings, and industry engagement can open unexpected doors, especially when you are fresh out of a data science course for freshers 2026 and building your professional network.
Picking a course based on price alone. The cheapest data science course for freshers 2026 is rarely the best value. Look at placement outcomes, mentor quality, and curriculum depth before making a decision.
Overloading on theory without practising coding. Data science is applied. Every concept you study should be followed by hands-on implementation in Python or SQL. If your data science course for freshers 2026 is lecture-heavy with minimal coding exercises, find a better one.
Ignoring communication skills. The best models in the world create zero value if you cannot explain your findings to a non-technical audience. Practice presenting your project results as if you were speaking to a business leader.
Skipping statistics. Many learners rush to neural networks before mastering linear regression. This creates fragile understanding. Build your statistical foundations before advancing — the right data science course for freshers 2026 will enforce this sequence.
Not networking. Attend data science meetups (DataHack Summit, NASSCOM events, local Kaggle meetups), join Discord and Slack communities, and reach out to data professionals on LinkedIn. Many jobs in India are still filled through referrals.
While a structured programme is essential, supplementing your data science course for freshers 2026 with quality free resources accelerates growth significantly:
The field is not static. As you build your initial skills through a data science course for freshers 2026, stay aware of where the profession is heading:
The fundamentals you build through a quality data science course for freshers 2026 — strong Python skills, statistical thinking, data intuition, and clear communication — will remain valuable regardless of which tools and platforms rise and fall over the next decade.
The demand for data professionals in India has never been higher, and the barriers to entry have never been lower. If you are a fresher in 2026 looking to break into this field, completing the right data science course for freshers 2026 gives you access to better opportunities, higher starting salaries, and a faster growth trajectory than almost any other technical path available today.
Be deliberate. Choose a data science course for freshers 2026 that is current, hands-on, and career-focused. Build real projects. Network consistently. And remember that every senior data scientist you admire today started exactly where you are now — staring at their first Python error message and deciding to figure it out.
Your data science career starts today. The industry is waiting.
Prateek Agrawal May 23, 2026 No Comments
Every few years, a technology arrives that genuinely changes the rules. Not incrementally but structurally. The internet changed how information moves. Smartphones changed how people interact with technology. Generative AI is doing something of the same order: it is changing what machines can do, and by extension, what humans need to do to remain relevant in the workforce.
But there is a confusion problem. When most people say “AI,” they are collapsing two fundamentally different categories of technology into one word. Traditional AI and generative AI are not the same thing. They work differently, they do different things, they are used differently by businesses, and they require different skills to work with.
If you are trying to understand where to invest your learning time in 2026 or simply trying to make sense of the technology reshaping your industry, understanding this distinction is the place to start.
This article will explain the difference clearly, without jargon, and connect it directly to what it means for careers in data science and analytics in India today.
Traditional AI, also called conventional AI, predictive AI, or narrow AI is the form of artificial intelligence that has been powering business decisions for the last two decades. It is the AI behind your bank’s fraud detection system, the recommendation engine on a streaming platform, the credit scoring model that decides loan eligibility, and the demand forecasting tool that tells a retailer how much stock to order next month.
Traditional AI works by learning patterns from historical data and using those patterns to make predictions or decisions about new data. Feed it millions of past loan applications labelled “default” or “no default,” and it learns to predict which future applications are risky. Feed it years of sales data and it learns to forecast what sales will look like next quarter. Feed it thousands of customer profiles labelled “churned” or “retained” and it learns to identify which current customers are most likely to leave.
The key characteristics of traditional AI are:
It is trained on labelled data. Most traditional AI models require human-labelled examples to learn from. Someone or a team of someones has to tag data as spam or not spam, fraudulent or legitimate, positive sentiment or negative sentiment. This labelling process is expensive, time-consuming, and a significant bottleneck.
It is narrow by design. A traditional AI model trained to detect credit card fraud cannot suddenly also predict customer churn. Each model is built for one specific task. It is extraordinarily good at that task, often better than humans but it cannot generalise beyond its training objective.
It produces predictions and classifications, not content. The output of a traditional AI model is typically a number, a category, or a probability. A fraud detection model outputs “fraud” or “not fraud.” A demand forecasting model outputs a sales number. A churn prediction model outputs a probability score. Traditional AI tells you what is likely to happen or what category something belongs to. It does not create anything new.
It is highly interpretable in well-designed systems. Many traditional AI models, particularly decision trees, logistic regression, and gradient boosting models can be examined to understand why they made a particular prediction. This interpretability is critically important in regulated industries like banking, insurance, and healthcare, where a decision must be explainable to a regulator or a customer.
Traditional AI has delivered enormous value across industries. It is not obsolete. It is not going away. But it has a hard ceiling and generative AI operates above that ceiling.
Generative AI is a fundamentally different category of artificial intelligence. Rather than learning patterns to make predictions about existing data, generative AI learns the underlying structure of data to create entirely new data that resembles what it was trained on.
The models at the heart of generative AI large language models like GPT-4o, Claude, and Gemini, image generation models like Stable Diffusion and DALL-E, and code generation tools like GitHub Copilot are trained on vast quantities of text, images, code, and other content. Through that training, they develop a deep statistical understanding of how human-created content is structured. They learn, in essence, the grammar of language, the composition rules of images, the syntax of code.
Then, given a prompt, they use that understanding to generate new content that follows those same structural patterns. The output is not retrieved from a database. It is not assembled from templates. It is created, token by token, word by word, pixel by pixel, from the model’s learned representation of how that type of content is typically constructed.
The key characteristics of generative AI are:
It is trained on unstructured data at massive scale. Unlike traditional AI, which typically requires carefully labelled datasets of thousands or millions of examples, generative AI models are pre-trained on trillions of tokens of raw text, images, and code scraped from the internet, books, academic papers, and other sources. This pre-training gives them broad, general knowledge across an enormous range of domains.
It is general-purpose within its modality. A large language model can write a legal brief, generate Python code, summarise a financial report, translate between languages, explain a scientific concept, and draft a marketing email all with the same model. This generality is unprecedented in AI history. Traditional AI models are specialists; generative AI models are generalists.
It produces content, not just predictions. The output of a generative AI system is new content: a paragraph of text, a piece of code, an image, a structured data object, a summary, a conversation. This is fundamentally different from the numerical outputs of traditional AI. Generative AI does not tell you what will happen — it creates something that did not previously exist.
It is directed through natural language. Traditional AI systems are configured through data pipelines, feature engineering, hyperparameter tuning, and code. Generative AI systems are directed through prompts — instructions written in natural language. This dramatically lowers the technical barrier to using AI, which is one of the reasons generative AI has spread so rapidly across non-technical business functions.
It is less inherently interpretable. The internal workings of a large language model involving billions or trillions of parameters — are substantially harder to interpret than a logistic regression or decision tree. This is a genuine limitation in high-stakes, regulated environments, and an active area of research in the field of AI explainability.
If you want to remember one thing from this article, let it be this:
Traditional AI predicts. Generative AI creates.
Traditional AI takes existing data and tells you instructions like this transaction is fraudulent, this customer will churn, this image contains a cat. It reasons from data to conclusions about data.
Generative AI takes a prompt and produces something new. A document, a piece of code, an analysis, a design or an answer. It reasons from patterns learned during training to generate content that has never existed before.
This distinction has profound implications for how each type of AI is used in business, and what skills professionals need to work effectively alongside each type.
The most sophisticated AI deployments in 2026 do not use traditional AI or generative AI, they use both, in complementary ways.
Consider a bank building a loan assessment system. Traditional AI handles the quantitative prediction: given an applicant’s financial history, employment record, and credit behaviour, what is the probability of default? The traditional model is narrow, precise, trained on millions of labelled examples, and auditable by regulators.
Generative AI handles the communication and augmentation layers: it generates a plain-language explanation of why the application was declined, drafts the letter sent to the applicant, helps the underwriter by summarising the applicant’s profile from documents, and assists the compliance team by answering questions about the decision in plain English.
Or consider an e-commerce company. Traditional AI powers the recommendation engine — predicting which products a user is most likely to purchase based on browsing history and purchase patterns. Generative AI writes personalised product descriptions, drafts promotional emails tailored to individual customer segments, generates responses to customer service queries, and helps the analytics team by producing natural-language summaries of sales performance reports.
The pattern repeats across industries: traditional AI for structured prediction tasks where accuracy, auditability, and domain specificity matter; generative AI for content generation, communication, synthesis, and augmentation tasks where flexibility and natural language capability matter.
For data professionals, this means the skill set in 2026 is additive. You need to understand traditional machine learning — how to build, evaluate, and deploy predictive models — and you need to understand generative AI — how to prompt, fine-tune, integrate, and build applications with large language models. These are not competing skill sets. They are layers of the same profession.
| Dimension | Traditional AI | Generative AI |
| Primary function | Predict, classify, detect | Create, generate, synthesise |
| Training data | Labelled, domain-specific | Vast unstructured text/images/code |
| Output type | Numbers, categories, scores | Text, code, images, structured data |
| Scope | Narrow — one task per model | General — many tasks, one model |
| How you interact | Code, pipelines, APIs | Natural language prompts |
| Interpretability | Often high (some models) | Lower — active research area |
| Examples | Fraud detection, churn prediction, demand forecasting, image classification | ChatGPT, Claude, Copilot, DALL-E, Gemini |
| Business use cases | Risk scoring, quality control, personalisation, predictive maintenance | Content generation, code assistance, document summarisation, customer support |
| Key skills needed | Statistics, ML algorithms, feature engineering, model evaluation | Prompt engineering, RAG, fine-tuning, agentic frameworks |
What This Means for Data Professionals in India
The data science profession in India is at an inflection point. The skills that defined a strong data scientist in 2020 — Python, SQL, machine learning, data visualisation — remain necessary but are no longer sufficient for professionals who want to stay at the front of the field.
The professionals who are commanding the highest salaries and the most interesting roles in 2026 are those who have added generative AI capabilities to a strong traditional ML foundation. They understand not just how to build a churn prediction model — but how to wrap that model in an AI assistant that helps business users interpret and act on its outputs. They know not just how to write SQL queries — but how to build a natural language interface that lets non-technical stakeholders query a database in plain English. They can not just build a data pipeline — they can augment it with AI agents that automatically flag anomalies, generate narrative summaries, and route insights to the right decision-makers.
This combination — traditional AI for structured analytical depth, generative AI for flexibility, communication, and automation — is what the market is calling “AI-augmented data science.” And it is the skill set that Ivy Professional School’s Generative AI and Data Science program is designed to build.
If you are a data professional trying to understand where to invest your learning time, here is the honest answer.
If you are new to data science entirely, start with the fundamentals: statistics, SQL, Python, and basic machine learning. These are the non-negotiables that underpin everything else. A professional who jumps straight to prompt engineering without understanding data structures, probability, and model evaluation is building on sand. The traditional AI foundation comes first.
If you already have data analytics or data science experience, the most valuable investment in 2026 is adding generative AI to your existing toolkit. Specifically: prompt engineering (how to direct large language models effectively), retrieval-augmented generation (how to connect LLMs to proprietary data sources), agentic AI frameworks (how to build AI systems that can complete multi-step tasks autonomously), and fine-tuning (when and how to customise a foundation model for a specific business use case).
If you are a business professional — not a data specialist — who wants to understand how AI applies to your domain, the generative AI layer is the most immediately accessible entry point. Prompt engineering, AI-assisted analysis, and understanding how to work alongside AI tools in your workflow do not require a deep statistical background. They require clear thinking, domain expertise, and structured communication skills that many non-technical professionals already possess.
At Ivy Professional School, we made a deliberate curriculum decision when the generative AI wave hit in 2023: we did not replace our traditional machine learning curriculum with a generative AI curriculum. We expanded it.
Because the professionals our 500+ hiring partners are looking for in 2026 are not specialists in one category or the other. They are professionals who understand the full landscape — who know when a problem calls for a predictive model and when it calls for a generative solution, who can build both and integrate them, and who can communicate about both to business stakeholders who need to trust and act on the outputs.
Our Generative AI and Data Science program — certified by E&ICT Academy, and backed by NASSCOM and IBM — covers traditional machine learning, data analytics, and the full generative AI stack: LLM fundamentals, prompt engineering, RAG architecture, agentic AI frameworks, and responsible AI. Students do not choose between traditional and generative AI. They learn both, applied to real business problems, in a structured sequence that builds genuine job-ready capability.
Across 37,500+ alumni over eighteen years, this integrated approach has consistently produced the placement outcomes that our students come for — and that our hiring partners return for year after year.
Traditional AI and generative AI are not competitors. They are not a generational replacement — one obsoleting the other. They are complementary technologies, each with its own strengths, appropriate use cases, and required skill sets.
Traditional AI is the engine of structured prediction: precise, narrow, auditable, and extraordinarily effective at the specific tasks it is designed for. Generative AI is the engine of creation and communication: flexible, general-purpose, and capable of working with language and unstructured information in ways that traditional AI fundamentally cannot.
The professionals who understand both — who can navigate the full landscape of modern AI, choosing the right tool for the right problem — are the ones the job market in India is competing for in 2026.
Understanding the difference is not just academic. It is the foundation of a career strategy.
Ivy Professional School’s Generative AI and Data Science program is designed for exactly the professional described in this article — someone who wants to understand and work with the full spectrum of modern AI, not just a slice of it.
NASSCOM and IBM backed. Pay After Placement. Weekend batches available across Kolkata and Bangalore.
Book a free counselling session at ivyproschool.com and speak with a program advisor who can map your current background to the fastest path to a job-ready AI skill set.
Q1. Is generative AI replacing traditional AI in data science jobs?
No — generative AI is augmenting traditional AI, not replacing it. Predictive modelling, classification, clustering, and anomaly detection remain core data science competencies in 2026. What has changed is that professionals who can also work with generative AI — building LLM-powered applications, designing prompt systems, and integrating AI into data workflows — command a significant salary premium over those who cannot. The floor has not moved; the ceiling has risen.
Q2. Do I need to learn traditional machine learning before generative AI?
For data science and analytics roles, yes — the traditional ML foundation matters. Understanding statistics, model evaluation, feature engineering, and data pipelines gives you the context to use generative AI tools correctly and critically. Without that foundation, you may produce faster outputs but you will lack the judgment to know whether those outputs are correct. For business analyst and non-technical roles, generative AI skills alone can be valuable entry points without a full ML background.
Q3. What are the most in-demand generative AI skills for data professionals in India?
In 2026, the skills generating the most employer demand across India’s data job market are: prompt engineering (structured and applied), retrieval-augmented generation (RAG) for enterprise knowledge bases, agentic AI workflow design using frameworks like LangChain and CrewAI, LLM fine-tuning for domain-specific applications, and responsible AI — understanding where generative models fail, hallucinate, or introduce bias, and building systems that manage those risks.
Q4. Which industries in India are adopting generative AI fastest?
BFSI (Banking, Financial Services, Insurance) leads adoption — using generative AI for document processing, regulatory compliance, customer communication, and fraud narrative generation alongside traditional fraud detection models. E-commerce and retail follow, using GenAI for personalised content, product descriptions, and customer support automation. Healthcare is growing fast, particularly in clinical documentation, medical coding, and patient communication. IT services and consulting have the broadest adoption simply due to their scale. In every case, traditional AI and generative AI are being deployed together, not as substitutes.
Q5. What salary can I expect after learning both traditional and generative AI skills?
Professionals who combine solid traditional machine learning competencies with generative AI skills are earning ₹10–20 LPA at fresher to junior levels in India’s top product companies, GCCs, and consulting firms in 2026. Mid-level professionals with three to five years of experience who add GenAI specialisation are seeing salary increments of 30–50% within twelve to eighteen months. The salary premium for GenAI-capable candidates over traditional ML-only candidates at equivalent experience levels is currently 25–45% — a gap that reflects the supply shortage in this combined skill set.
Prateek Agrawal May 02, 2026 No Comments
Prateek Agrawal Apr 28, 2026 No Comments