Prateek Agrawal Jul 25, 2026 No Comments
AI business automation is no longer a buzzword reserved for Silicon Valley giants, it is the single biggest competitive advantage available to businesses of every size in 2026. From automating customer support tickets to predicting inventory demand, AI business automation is transforming how companies operate, cutting costs, saving time, and unlocking growth that simply wasn’t possible with manual processes. If you are a business owner, a working professional, or someone exploring a career shift into technology, understanding AI business automation is no longer optional, it’s essential.
In this guide, we’ll break down what AI business automation actually means, why it matters, how companies across industries are using it, the tools driving this revolution, and how you can build the skills to lead this transformation yourself.
AI business automation refers to the use of artificial intelligence technologies — including machine learning, natural language processing, computer vision, and generative AI — to automate repetitive, rule-based, and even complex decision-making tasks within a business. Unlike traditional automation, which follows fixed, pre-programmed rules, AI business automation systems learn from data, adapt to new situations, and improve over time.
Think of traditional automation as a simple “if this, then that” system. AI business automation, on the other hand, can read an email, understand its intent, decide the right department to route it to, draft a response, and even flag it for human review if the sentiment suggests urgency — all without a human lifting a finger. This is the fundamental shift that makes AI business automation so powerful for modern businesses.
The demand for AI business automation has exploded because businesses today are under pressure to do more with less. Here’s why companies are racing to adopt AI business automation solutions:
AI business automation significantly reduces operational costs by minimizing the need for manual labor on repetitive tasks like data entry, invoice processing, and customer query resolution.
Tasks that once took days can now be completed in minutes. AI business automation tools process thousands of transactions, emails, or records simultaneously — something no human team could match.
Human error is one of the costliest problems in business operations. AI business automation dramatically reduces mistakes in data processing, reporting, and compliance-related tasks.
With AI business automation, businesses can offer 24/7 customer support through chatbots, personalized recommendations, and instant query resolution — improving customer satisfaction and retention.
As your business grows, AI business automation scales with you without the need to proportionally increase your workforce, making it a critical tool for startups and SMEs looking to expand efficiently.
One of the most visible applications of AI business automation is in customer service. AI-powered chatbots and virtual assistants can now handle a majority of customer queries without human intervention, using natural language processing to understand context and intent. This form of AI business automation allows human agents to focus on complex, high-value interactions while routine questions are resolved instantly.
AI business automation has transformed digital marketing. Predictive analytics tools use AI to identify which leads are most likely to convert, allowing sales teams to prioritize their efforts. Email marketing platforms use AI business automation to personalize content, subject lines, and send times for each subscriber, dramatically improving open and conversion rates.
From automated invoice processing to fraud detection, AI business automation is reshaping finance departments. AI systems can flag anomalies in transactions, reconcile accounts, and even generate financial forecasts — tasks that once required entire teams of analysts.
AI business automation tools now screen resumes, schedule interviews, and even conduct preliminary candidate assessments. This doesn’t just save HR teams time — it also helps remove unconscious bias from the hiring process when implemented correctly.
Retail and manufacturing businesses are increasingly relying on AI business automation to predict demand, optimize inventory levels, and manage logistics. AI-driven supply chain automation minimizes stockouts and overstocking, directly improving profitability.
AI business automation tools like intelligent document processing (IDP) can extract, classify, and process information from invoices, contracts, and forms with minimal human oversight, saving businesses countless hours of manual data entry.
Understanding the tools behind AI business automation helps professionals and businesses choose the right stack for their needs:
Learning to work with these tools is quickly becoming a core skill expectation across marketing, operations, HR, and finance roles — which is exactly why AI business automation training has become one of the most in-demand skill areas today.
Imagine a small e-commerce business struggling to manage customer queries, inventory tracking, and marketing campaigns with a lean team. By implementing AI business automation:
This is the real, tangible power of AI business automation — it isn’t just for large corporations. Small and medium businesses stand to gain the most because AI business automation levels the playing field, allowing lean teams to compete with much larger organizations.
While the benefits are massive, implementing AI business automation isn’t without hurdles:
The good news? Most of these challenges are solved not by better software alone, but by better-trained people who understand how to strategically implement AI business automation within an organization.
Given how rapidly AI business automation is being adopted across industries, professionals who understand how to design, implement, and manage these systems are in extremely high demand. Whether you’re a marketer, an analyst, an entrepreneur, or a fresh graduate, developing skills in AI business automation can significantly boost your career prospects.
Here’s what you typically need to get started in AI business automation:
This is precisely the gap that Ivy Pro School’s Generative AI Course is designed to fill. The course is built for professionals and entrepreneurs who want to master AI business automation, generative AI tools, and practical implementation strategies — not just theory. With a curriculum covering real-world automation case studies, hands-on projects, and tools that businesses are actively using today, learners walk away with the confidence to lead AI business automation initiatives in their own organizations.
For entrepreneurs and business owners specifically, Ivy Pro School’s AI for Entrepreneurs Course, led by industry expert Prateek Agrawal, is tailored to help you apply AI business automation directly to your business — whether that’s automating customer service, marketing, operations, or financial processes. Instead of generic AI theory, this course focuses on practical, business-first applications of AI business automation that you can implement immediately.
Both programs come with the backing of a Pay After Placement option, access to the proprietary PrepAI tool for interview preparation, and the support of a thriving community of 37,500+ alumni and 500+ hiring partners — giving learners not just knowledge of AI business automation, but a genuine career and business growth pathway.
Looking ahead, AI business automation is expected to become even more deeply embedded into everyday business operations. Here’s what to expect:
The next wave of AI business automation involves autonomous AI agents that can execute multi-step tasks — from researching a topic to drafting a report to sending it for approval — with minimal human input.
AI business automation will increasingly allow businesses to deliver hyper-personalized experiences at scale, tailoring everything from product recommendations to pricing based on individual customer behavior.
As AI business automation platforms become more user-friendly, business teams without technical backgrounds will be able to build and deploy sophisticated automation workflows themselves.
Expect AI business automation solutions tailored specifically for healthcare, legal, real estate, and other niche industries, offering deeper domain-specific value than generic tools.
As AI business automation adoption grows, so will the need for ethical guidelines, data privacy safeguards, and responsible AI governance frameworks within organizations.
Q1: What is AI business automation in simple terms? AI business automation is the use of artificial intelligence to handle business tasks — like answering customer queries, processing data, or managing marketing campaigns — automatically and intelligently, without constant human supervision.
Q2: Is AI business automation only for large companies? No. In fact, AI business automation often delivers the biggest relative benefit to small and medium businesses, since it allows lean teams to accomplish more without hiring additional staff.
Q3: Will AI business automation replace human jobs? AI business automation tends to replace repetitive tasks rather than entire jobs. It shifts human focus toward higher-value, creative, and strategic work while automating routine processes.
Q4: What skills do I need to work in AI business automation? You’ll need a foundational understanding of AI and machine learning, hands-on experience with automation and generative AI tools, and the business judgment to identify where automation adds real value — all of which are covered in Ivy Pro School’s Generative AI Course and AI for Entrepreneurs Course.
Q5: How much does it cost to implement AI business automation? Costs vary widely depending on the scale and complexity of the AI business automation system, ranging from free or low-cost no-code tools to enterprise-grade platforms requiring significant investment.
Q6: How long does it take to learn AI business automation? With a structured, hands-on program like the courses offered at Ivy Pro School, most learners can build practical AI business automation skills within a few months, depending on prior experience and time commitment.
AI business automation is fundamentally reshaping how businesses operate — from customer service and marketing to finance and supply chain management. The organizations and professionals who understand how to strategically implement AI business automation today will be the ones leading their industries tomorrow.
Whether you’re a business owner looking to streamline operations or a professional aiming to future-proof your career, now is the time to invest in AI business automation skills. Explore Ivy Pro School’s Generative AI Course or the AI for Entrepreneurs Course with Prateek Agrawal, and take the first step toward mastering AI business automation for real-world impact.
Prateek Agrawal May 30, 2026 No Comments
If you are a fresh graduate wondering where to begin, enrolling in a data science course for freshers 2026 could be the single most impactful career decision you make this year. India’s data economy is expanding at an extraordinary pace, and employers across Bangalore, Hyderabad, Pune, and Mumbai are actively hunting for entry-level talent who can work with data confidently. The right data science course for freshers 2026 will equip you with Python, machine learning, SQL, and cloud skills that today’s recruiters actually demand. This guide walks you through everything you need to know: what to learn, where to learn it, how much you can earn, and what the job market truly looks like this year.
The Indian data analytics market was valued at over ₹84,000 crore in 2024 and is projected to cross ₹2,00,000 crore by 2028. Behind those numbers are millions of job roles, data analysts, machine learning engineers, business intelligence developers, data engineers, and AI specialists, many of which remain unfilled because the supply of trained professionals simply cannot keep up with demand. This is precisely why a data science course for freshers 2026 has become one of the most searched career-launch decisions among Indian graduates today.
What changed between 2022 and 2026? Three significant things:
Generative AI has become mainstream. Every company, from a Tier-2 SaaS startup to a large public-sector bank, now needs professionals who understand both traditional data pipelines and large language model (LLM) integrations. Any data science course for freshers in 2026 that does not cover generative AI fundamentals is already outdated. Entry-level candidates who know how to work alongside AI tools are considered far more hireable than those who do not.
The cloud-first economy has deepened. AWS, Google Cloud, and Microsoft Azure are now foundational infrastructure for most Indian businesses. A data science course for freshers 2026 should include at least a module on cloud-based data storage, processing, and model deployment to remain industry-relevant.
Tier-2 cities have opened up. Remote and hybrid work has democratised opportunity. Companies are now hiring data professionals from Jaipur, Coimbatore, Nagpur, and Bhopal, not just the traditional tech metros. This means a fresher anywhere in India can access the same quality of roles as someone sitting in Bengaluru, provided their skills are sharp.
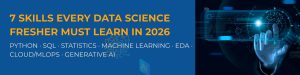
A well-structured data science course for freshers 2026 is not the same as it was even three years ago. The curriculum has evolved significantly to reflect new tools, new employer expectations, and new technologies. Here is what a modern, industry-aligned programme should include:
Python remains the dominant language in data science, and for good reason it is versatile, readable, and supported by an enormous ecosystem of libraries. A good data science course for freshers 2026 will start you with Python basics, data types, loops, functions, file handling, before moving into data-specific libraries:
SQL is equally non-negotiable. Almost every real-world data role requires writing queries to extract and transform data from relational databases. Look for a data science course for freshers 2026 that spends at least 20–30 dedicated hours on SQL, covering joins, subqueries, window functions, and query optimisation.
One of the biggest mistakes freshers make is skipping the mathematical foundations in favour of jumping straight to model-building. Statistics forms the backbone of every machine learning technique, and the best data science course for freshers 2026 will make sure you understand it deeply. A solid programme covers:
You do not need to be a mathematician, but you do need enough statistical intuition to interpret results correctly and avoid common modelling pitfalls.
This is the core of most programmes. A complete data science course for freshers 2026 should cover both supervised and unsupervised learning:
In 2026, a competitive data science course for freshers will also introduce deep learning fundamentals — neural networks, CNNs, and RNNs — along with an introduction to transformer architectures, which underpin most modern AI systems.
Raw data is almost always messy. A significant portion of a practising data scientist’s time goes into cleaning, transforming, and understanding data before any model is built. The best data science course for freshers 2026 simulates this reality with messy, real-world datasets rather than polished toy examples, so you are prepared for what actual work looks like.
Being able to build a model is only half the job. Communicating findings to non-technical stakeholders such as product managers, business heads, CFOs is equally important. A strong data science course for freshers 2026 will include tools like:
Modern data science does not end at a Jupyter notebook. Freshers are now expected to understand how models get deployed and maintained in production. A forward-looking data science course for freshers 2026 should introduce:
This is the newest — and most exciting — addition to entry-level curricula. Understanding how to use APIs like OpenAI or Claude, build simple RAG (Retrieval Augmented Generation) pipelines, and work with vector databases is fast becoming a standard expectation. Any data science course for freshers 2026 worth your money will include at least an introductory module on generative AI tools and workflows.
With hundreds of options available, from 12-week bootcamps to two-year postgraduate programmes — choosing the right data science course for freshers 2026 is critical. Here are the factors that should guide your decision:
Check when the syllabus was last updated. A data science course for freshers designed in 2021 will not cover generative AI, modern MLOps tools, or the latest industry frameworks. Ask the provider directly or look for syllabi published on their website. If the course still treats deep learning as “advanced optional content,” move on.
Recruiters in India’s data science market care far more about your portfolio than your certificates. A strong data science course for freshers 2026 should include at least 3–5 end-to-end projects on real datasets — ideally across different domains such as finance, healthcare, e-commerce, and logistics.
Look for programmes that offer live sessions with industry practitioners, code reviews, and dedicated placement assistance. Mock interviews, resume workshops, and access to hiring networks significantly increase your chances of landing your first role after completing a data science course for freshers 2026.
For freshers with no prior background, a programme of 6–12 months is typically necessary to build genuine proficiency. Shorter crash courses may introduce concepts but rarely produce job-ready candidates. When evaluating a data science course for freshers 2026, ask providers for placement statistics — specifically median time-to-hire and average starting salary — before enrolling.
Reputable programmes in India range from ₹30,000 for self-paced online courses to ₹3,00,000 or more for full-time immersive bootcamps with placement guarantees. Many platforms offering a data science course for freshers 2026 also provide EMI options, income-share agreements, or merit-based scholarships.
Understanding the landscape before you enter it saves time and helps you target the right roles.
Bengaluru leads as India’s data science hub, but Hyderabad, Pune, Chennai, and the NCR (Noida and Gurugram) are all strong markets. In 2026, remote-first roles are especially common in product companies and global capability centres (GCCs), giving freshers outside metros genuine opportunities without relocating — provided they have completed a solid data science course for freshers 2026 that prepared them for independent work.
A certificate alone will not get you an interview. What matters is proof that you can apply your skills to real problems. The best data science course for freshers 2026 will help you build this portfolio as part of the programme, but here is how to go further:
Every project should be uploaded to GitHub with a clear README explaining the business problem, methodology, key findings, and model performance metrics. Kaggle competitions are an excellent way to benchmark your skills — even a top-50% finish on a public competition demonstrates that you can work with messy, real data under defined objectives.
Writing about what you learn — a tutorial, a case study, a model explainer — signals communication skills and genuine intellectual curiosity. A consistent LinkedIn presence showing your projects, learnings, and industry engagement can open unexpected doors, especially when you are fresh out of a data science course for freshers 2026 and building your professional network.
Picking a course based on price alone. The cheapest data science course for freshers 2026 is rarely the best value. Look at placement outcomes, mentor quality, and curriculum depth before making a decision.
Overloading on theory without practising coding. Data science is applied. Every concept you study should be followed by hands-on implementation in Python or SQL. If your data science course for freshers 2026 is lecture-heavy with minimal coding exercises, find a better one.
Ignoring communication skills. The best models in the world create zero value if you cannot explain your findings to a non-technical audience. Practice presenting your project results as if you were speaking to a business leader.
Skipping statistics. Many learners rush to neural networks before mastering linear regression. This creates fragile understanding. Build your statistical foundations before advancing — the right data science course for freshers 2026 will enforce this sequence.
Not networking. Attend data science meetups (DataHack Summit, NASSCOM events, local Kaggle meetups), join Discord and Slack communities, and reach out to data professionals on LinkedIn. Many jobs in India are still filled through referrals.
While a structured programme is essential, supplementing your data science course for freshers 2026 with quality free resources accelerates growth significantly:
The field is not static. As you build your initial skills through a data science course for freshers 2026, stay aware of where the profession is heading:
The fundamentals you build through a quality data science course for freshers 2026 — strong Python skills, statistical thinking, data intuition, and clear communication — will remain valuable regardless of which tools and platforms rise and fall over the next decade.
The demand for data professionals in India has never been higher, and the barriers to entry have never been lower. If you are a fresher in 2026 looking to break into this field, completing the right data science course for freshers 2026 gives you access to better opportunities, higher starting salaries, and a faster growth trajectory than almost any other technical path available today.
Be deliberate. Choose a data science course for freshers 2026 that is current, hands-on, and career-focused. Build real projects. Network consistently. And remember that every senior data scientist you admire today started exactly where you are now — staring at their first Python error message and deciding to figure it out.
Your data science career starts today. The industry is waiting.

Prateek Agrawal May 23, 2026 No Comments
Every few years, a technology arrives that genuinely changes the rules. Not incrementally but structurally. The internet changed how information moves. Smartphones changed how people interact with technology. Generative AI is doing something of the same order: it is changing what machines can do, and by extension, what humans need to do to remain relevant in the workforce.
But there is a confusion problem. When most people say “AI,” they are collapsing two fundamentally different categories of technology into one word. Traditional AI and generative AI are not the same thing. They work differently, they do different things, they are used differently by businesses, and they require different skills to work with.
If you are trying to understand where to invest your learning time in 2026 or simply trying to make sense of the technology reshaping your industry, understanding this distinction is the place to start.
This article will explain the difference clearly, without jargon, and connect it directly to what it means for careers in data science and analytics in India today.
Traditional AI, also called conventional AI, predictive AI, or narrow AI is the form of artificial intelligence that has been powering business decisions for the last two decades. It is the AI behind your bank’s fraud detection system, the recommendation engine on a streaming platform, the credit scoring model that decides loan eligibility, and the demand forecasting tool that tells a retailer how much stock to order next month.
Traditional AI works by learning patterns from historical data and using those patterns to make predictions or decisions about new data. Feed it millions of past loan applications labelled “default” or “no default,” and it learns to predict which future applications are risky. Feed it years of sales data and it learns to forecast what sales will look like next quarter. Feed it thousands of customer profiles labelled “churned” or “retained” and it learns to identify which current customers are most likely to leave.
The key characteristics of traditional AI are:
It is trained on labelled data. Most traditional AI models require human-labelled examples to learn from. Someone or a team of someones has to tag data as spam or not spam, fraudulent or legitimate, positive sentiment or negative sentiment. This labelling process is expensive, time-consuming, and a significant bottleneck.
It is narrow by design. A traditional AI model trained to detect credit card fraud cannot suddenly also predict customer churn. Each model is built for one specific task. It is extraordinarily good at that task, often better than humans but it cannot generalise beyond its training objective.
It produces predictions and classifications, not content. The output of a traditional AI model is typically a number, a category, or a probability. A fraud detection model outputs “fraud” or “not fraud.” A demand forecasting model outputs a sales number. A churn prediction model outputs a probability score. Traditional AI tells you what is likely to happen or what category something belongs to. It does not create anything new.
It is highly interpretable in well-designed systems. Many traditional AI models, particularly decision trees, logistic regression, and gradient boosting models can be examined to understand why they made a particular prediction. This interpretability is critically important in regulated industries like banking, insurance, and healthcare, where a decision must be explainable to a regulator or a customer.
Traditional AI has delivered enormous value across industries. It is not obsolete. It is not going away. But it has a hard ceiling and generative AI operates above that ceiling.
Generative AI is a fundamentally different category of artificial intelligence. Rather than learning patterns to make predictions about existing data, generative AI learns the underlying structure of data to create entirely new data that resembles what it was trained on.
The models at the heart of generative AI large language models like GPT-4o, Claude, and Gemini, image generation models like Stable Diffusion and DALL-E, and code generation tools like GitHub Copilot are trained on vast quantities of text, images, code, and other content. Through that training, they develop a deep statistical understanding of how human-created content is structured. They learn, in essence, the grammar of language, the composition rules of images, the syntax of code.
Then, given a prompt, they use that understanding to generate new content that follows those same structural patterns. The output is not retrieved from a database. It is not assembled from templates. It is created, token by token, word by word, pixel by pixel, from the model’s learned representation of how that type of content is typically constructed.
The key characteristics of generative AI are:
It is trained on unstructured data at massive scale. Unlike traditional AI, which typically requires carefully labelled datasets of thousands or millions of examples, generative AI models are pre-trained on trillions of tokens of raw text, images, and code scraped from the internet, books, academic papers, and other sources. This pre-training gives them broad, general knowledge across an enormous range of domains.
It is general-purpose within its modality. A large language model can write a legal brief, generate Python code, summarise a financial report, translate between languages, explain a scientific concept, and draft a marketing email all with the same model. This generality is unprecedented in AI history. Traditional AI models are specialists; generative AI models are generalists.
It produces content, not just predictions. The output of a generative AI system is new content: a paragraph of text, a piece of code, an image, a structured data object, a summary, a conversation. This is fundamentally different from the numerical outputs of traditional AI. Generative AI does not tell you what will happen — it creates something that did not previously exist.
It is directed through natural language. Traditional AI systems are configured through data pipelines, feature engineering, hyperparameter tuning, and code. Generative AI systems are directed through prompts — instructions written in natural language. This dramatically lowers the technical barrier to using AI, which is one of the reasons generative AI has spread so rapidly across non-technical business functions.
It is less inherently interpretable. The internal workings of a large language model involving billions or trillions of parameters — are substantially harder to interpret than a logistic regression or decision tree. This is a genuine limitation in high-stakes, regulated environments, and an active area of research in the field of AI explainability.
If you want to remember one thing from this article, let it be this:
Traditional AI predicts. Generative AI creates.
Traditional AI takes existing data and tells you instructions like this transaction is fraudulent, this customer will churn, this image contains a cat. It reasons from data to conclusions about data.
Generative AI takes a prompt and produces something new. A document, a piece of code, an analysis, a design or an answer. It reasons from patterns learned during training to generate content that has never existed before.
This distinction has profound implications for how each type of AI is used in business, and what skills professionals need to work effectively alongside each type.
The most sophisticated AI deployments in 2026 do not use traditional AI or generative AI, they use both, in complementary ways.
Consider a bank building a loan assessment system. Traditional AI handles the quantitative prediction: given an applicant’s financial history, employment record, and credit behaviour, what is the probability of default? The traditional model is narrow, precise, trained on millions of labelled examples, and auditable by regulators.
Generative AI handles the communication and augmentation layers: it generates a plain-language explanation of why the application was declined, drafts the letter sent to the applicant, helps the underwriter by summarising the applicant’s profile from documents, and assists the compliance team by answering questions about the decision in plain English.
Or consider an e-commerce company. Traditional AI powers the recommendation engine — predicting which products a user is most likely to purchase based on browsing history and purchase patterns. Generative AI writes personalised product descriptions, drafts promotional emails tailored to individual customer segments, generates responses to customer service queries, and helps the analytics team by producing natural-language summaries of sales performance reports.
The pattern repeats across industries: traditional AI for structured prediction tasks where accuracy, auditability, and domain specificity matter; generative AI for content generation, communication, synthesis, and augmentation tasks where flexibility and natural language capability matter.
For data professionals, this means the skill set in 2026 is additive. You need to understand traditional machine learning — how to build, evaluate, and deploy predictive models — and you need to understand generative AI — how to prompt, fine-tune, integrate, and build applications with large language models. These are not competing skill sets. They are layers of the same profession.
| Dimension | Traditional AI | Generative AI |
| Primary function | Predict, classify, detect | Create, generate, synthesise |
| Training data | Labelled, domain-specific | Vast unstructured text/images/code |
| Output type | Numbers, categories, scores | Text, code, images, structured data |
| Scope | Narrow — one task per model | General — many tasks, one model |
| How you interact | Code, pipelines, APIs | Natural language prompts |
| Interpretability | Often high (some models) | Lower — active research area |
| Examples | Fraud detection, churn prediction, demand forecasting, image classification | ChatGPT, Claude, Copilot, DALL-E, Gemini |
| Business use cases | Risk scoring, quality control, personalisation, predictive maintenance | Content generation, code assistance, document summarisation, customer support |
| Key skills needed | Statistics, ML algorithms, feature engineering, model evaluation | Prompt engineering, RAG, fine-tuning, agentic frameworks |
What This Means for Data Professionals in India
The data science profession in India is at an inflection point. The skills that defined a strong data scientist in 2020 — Python, SQL, machine learning, data visualisation — remain necessary but are no longer sufficient for professionals who want to stay at the front of the field.
The professionals who are commanding the highest salaries and the most interesting roles in 2026 are those who have added generative AI capabilities to a strong traditional ML foundation. They understand not just how to build a churn prediction model — but how to wrap that model in an AI assistant that helps business users interpret and act on its outputs. They know not just how to write SQL queries — but how to build a natural language interface that lets non-technical stakeholders query a database in plain English. They can not just build a data pipeline — they can augment it with AI agents that automatically flag anomalies, generate narrative summaries, and route insights to the right decision-makers.
This combination — traditional AI for structured analytical depth, generative AI for flexibility, communication, and automation — is what the market is calling “AI-augmented data science.” And it is the skill set that Ivy Professional School’s Generative AI and Data Science program is designed to build.
If you are a data professional trying to understand where to invest your learning time, here is the honest answer.
If you are new to data science entirely, start with the fundamentals: statistics, SQL, Python, and basic machine learning. These are the non-negotiables that underpin everything else. A professional who jumps straight to prompt engineering without understanding data structures, probability, and model evaluation is building on sand. The traditional AI foundation comes first.
If you already have data analytics or data science experience, the most valuable investment in 2026 is adding generative AI to your existing toolkit. Specifically: prompt engineering (how to direct large language models effectively), retrieval-augmented generation (how to connect LLMs to proprietary data sources), agentic AI frameworks (how to build AI systems that can complete multi-step tasks autonomously), and fine-tuning (when and how to customise a foundation model for a specific business use case).
If you are a business professional — not a data specialist — who wants to understand how AI applies to your domain, the generative AI layer is the most immediately accessible entry point. Prompt engineering, AI-assisted analysis, and understanding how to work alongside AI tools in your workflow do not require a deep statistical background. They require clear thinking, domain expertise, and structured communication skills that many non-technical professionals already possess.
At Ivy Professional School, we made a deliberate curriculum decision when the generative AI wave hit in 2023: we did not replace our traditional machine learning curriculum with a generative AI curriculum. We expanded it.
Because the professionals our 500+ hiring partners are looking for in 2026 are not specialists in one category or the other. They are professionals who understand the full landscape — who know when a problem calls for a predictive model and when it calls for a generative solution, who can build both and integrate them, and who can communicate about both to business stakeholders who need to trust and act on the outputs.
Our Generative AI and Data Science program — certified by E&ICT Academy, and backed by NASSCOM and IBM — covers traditional machine learning, data analytics, and the full generative AI stack: LLM fundamentals, prompt engineering, RAG architecture, agentic AI frameworks, and responsible AI. Students do not choose between traditional and generative AI. They learn both, applied to real business problems, in a structured sequence that builds genuine job-ready capability.
Across 37,500+ alumni over eighteen years, this integrated approach has consistently produced the placement outcomes that our students come for — and that our hiring partners return for year after year.
Traditional AI and generative AI are not competitors. They are not a generational replacement — one obsoleting the other. They are complementary technologies, each with its own strengths, appropriate use cases, and required skill sets.
Traditional AI is the engine of structured prediction: precise, narrow, auditable, and extraordinarily effective at the specific tasks it is designed for. Generative AI is the engine of creation and communication: flexible, general-purpose, and capable of working with language and unstructured information in ways that traditional AI fundamentally cannot.
The professionals who understand both — who can navigate the full landscape of modern AI, choosing the right tool for the right problem — are the ones the job market in India is competing for in 2026.
Understanding the difference is not just academic. It is the foundation of a career strategy.
Ivy Professional School’s Generative AI and Data Science program is designed for exactly the professional described in this article — someone who wants to understand and work with the full spectrum of modern AI, not just a slice of it.
NASSCOM and IBM backed. Pay After Placement. Weekend batches available across Kolkata and Bangalore.
Book a free counselling session at ivyproschool.com and speak with a program advisor who can map your current background to the fastest path to a job-ready AI skill set.
Q1. Is generative AI replacing traditional AI in data science jobs?
No — generative AI is augmenting traditional AI, not replacing it. Predictive modelling, classification, clustering, and anomaly detection remain core data science competencies in 2026. What has changed is that professionals who can also work with generative AI — building LLM-powered applications, designing prompt systems, and integrating AI into data workflows — command a significant salary premium over those who cannot. The floor has not moved; the ceiling has risen.
Q2. Do I need to learn traditional machine learning before generative AI?
For data science and analytics roles, yes — the traditional ML foundation matters. Understanding statistics, model evaluation, feature engineering, and data pipelines gives you the context to use generative AI tools correctly and critically. Without that foundation, you may produce faster outputs but you will lack the judgment to know whether those outputs are correct. For business analyst and non-technical roles, generative AI skills alone can be valuable entry points without a full ML background.
Q3. What are the most in-demand generative AI skills for data professionals in India?
In 2026, the skills generating the most employer demand across India’s data job market are: prompt engineering (structured and applied), retrieval-augmented generation (RAG) for enterprise knowledge bases, agentic AI workflow design using frameworks like LangChain and CrewAI, LLM fine-tuning for domain-specific applications, and responsible AI — understanding where generative models fail, hallucinate, or introduce bias, and building systems that manage those risks.
Q4. Which industries in India are adopting generative AI fastest?
BFSI (Banking, Financial Services, Insurance) leads adoption — using generative AI for document processing, regulatory compliance, customer communication, and fraud narrative generation alongside traditional fraud detection models. E-commerce and retail follow, using GenAI for personalised content, product descriptions, and customer support automation. Healthcare is growing fast, particularly in clinical documentation, medical coding, and patient communication. IT services and consulting have the broadest adoption simply due to their scale. In every case, traditional AI and generative AI are being deployed together, not as substitutes.
Q5. What salary can I expect after learning both traditional and generative AI skills?
Professionals who combine solid traditional machine learning competencies with generative AI skills are earning ₹10–20 LPA at fresher to junior levels in India’s top product companies, GCCs, and consulting firms in 2026. Mid-level professionals with three to five years of experience who add GenAI specialisation are seeing salary increments of 30–50% within twelve to eighteen months. The salary premium for GenAI-capable candidates over traditional ML-only candidates at equivalent experience levels is currently 25–45% — a gap that reflects the supply shortage in this combined skill set.
Prateek Agrawal May 02, 2026 No Comments
Prateek Agrawal Apr 25, 2026 No Comments
Team Jan 11, 2023 No Comments



Team Dec 15, 2022 No Comments
Team Nov 24, 2022 No Comments
Team Oct 11, 2022 No Comments

